
原文:Context engineering: memory, compaction, and tool clearing(platform.claude.com Claude Cookbook,2026-03-20,作者 Isabella He)。本文为中文翻译,插图来自原文。
引言
构建长时程(long-horizon)代理时,一个常见的挑战是管理上下文。工具结果、模型自身的推理以及用户消息都会不断累积,最终要么撞上词元(token)上限,要么开始为已经帮不上忙的上下文付费。针对”大海捞针”(needle-in-a-haystack)式基准测试的研究揭示了上下文衰退(context rot)的概念:**随着上下文窗口中词元数量的增加,模型准确回忆其中信息的能力会下降。**因此,即使在到达硬性上下文上限之前,代理从每个词元中获得的收益也可能已经在减少。
我们关于AI 代理的有效上下文工程的工程博客将这个问题归结为资源问题:上下文是有限的,且边际收益递减;核心的纪律在于找到最小的高信号(signal)词元集合,以最大化期望结果的概率。实现这一点有多种杠杆:用子代理(subagent)把工作隔离在各自的上下文中,用程序化工具调用(programmatic tool calling)把大型结果完全挡在窗口之外,等等。
本 Cookbook 聚焦其中三种:压缩(compaction)、工具结果清理(tool-result clearing)和记忆(memory)。三者都是有效的上下文工程策略,但由于它们以不同的方式让上下文窗口变得更高效,彼此之间往往难以区分。理解这些差异,才能把每种工具映射到你工作负载中它真正起作用的那一部分。与利用子代理等其他核心上下文管理策略一样,这三种策略对于构建长期运行的代理的团队来说至关重要。而且它们都有一方 API(Anthropic 官方 API)的一等支持,你可以直接采用,无需自己搭建编排(orchestration)基础设施。
- 压缩把上下文窗口的内容提炼成高保真摘要,让对话变长时代理仍能以极小的性能损失继续运行。
- 工具结果清理针对的是工具使用本身造成的膨胀。代理接入工具并调用它们时,结果会不断堆积;决定保留多少工具输出,日益成为管理上下文的重要一环。清理会丢弃旧的、可重新获取的结果,同时保留”发生过这次调用”的记录。
- 记忆是一种结构化记笔记(structured note-taking):代理把笔记写入持久化的外部存储,这样不必把一切都放在活跃上下文中,也能跨任务、跨会话追踪进度。
Claude Code在生产环境中就采用了其中多种策略:用压缩处理长对话,并用两套互补的记忆系统实现跨会话持久化。我们的 API 为三者都提供了官方实现:服务端压缩、上下文编辑(context editing)(包含工具结果清理)以及记忆工具(memory tool)。本 Cookbook 将系统梳理围绕这些工具进行设计时应有的思考方式:各自适用于什么场景、如何配置、单独使用与组合使用分别会带来什么变化,以及不同组合适用的示例用例。
示例围绕一个**长期运行的研究代理(research agent)**展开:它阅读一批文档、做笔记,并跨多个会话在发现的基础上继续推进。这是一个有用的测试用例,因为它天然会撞上全部三类问题:大量的文档读取(对应清理)、漫长的分析对话(对应压缩),以及需要在会话之间存续的知识(对应记忆)。
你将学到什么
- 当代理的上下文被大型、可重新获取的工具结果(如文件读取、API 响应)占据时,如何用
clear_tool_uses限制会话内的词元增长 - 如何用服务端压缩让长对话继续下去,包括如何把压缩块(compaction block)序列化回去,以及如何探查摘要中幸存下来的内容
- 如何通过实现一个由模型自己驱动的、基于文件的记忆处理器(memory handler)来跨会话持久化代理知识,让会话 2 接着会话 1 的进度继续
- 如何最有效地实现每种原语(primitive):替换默认压缩提示词以保留你的代理所需的内容、引导代理往
/memories里写什么、并针对你自己工作负载的工具使用模式测试清理配置 - 如何诊断你的工作负载实际遇到的是哪一类上下文问题,并选出对症的原语——给出一个把工作负载特征映射到正确工具的框架
前置条件
要运行这个 notebook,你需要:
- 把 Anthropic API 密钥设为环境变量
ANTHROPIC_API_KEY,或放在.env文件中(在此获取) - 安装 Python 3.11+,以及
anthropic、python-dotenv、matplotlib包 - 与 notebook 同目录的
research_corpus.py(包含在仓库中)。它定义了CORPUS,一个由八篇关于衰老研究模式生物(model organisms)的合成综述文档构成的字典(每篇约 4 万词元,共约 32 万词元),以及稍后用来测试什么能在压缩后幸存的探查问题。你可以替换该字典,换成自己的文档。
**从 cookbooks 仓库运行?**请确保在运行 notebook 前把工作目录切到
tool_use/context_engineering。
第 0 步:环境设置
在本目录创建一个包含你的 Anthropic API 密钥的 .env 文件:
ANTHROPIC_API_KEY=your-key-here%%capture%pip install anthropic python-dotenv matplotlibimport jsonimport osimport tempfilefrom collections import namedtuplefrom pathlib import Path
import anthropicimport matplotlib.pyplot as pltfrom dotenv import load_dotenv
load_dotenv()
if not os.environ.get("ANTHROPIC_API_KEY"): raise ValueError("ANTHROPIC_API_KEY not set. Add it to a .env file or export it.")
CORPUS_PATH = Path("research_corpus.py")assert CORPUS_PATH.exists(), ( f"research_corpus.py not found in {Path.cwd()}. It should be alongside this notebook.")
client = anthropic.Anthropic()MODEL = "claude-sonnet-4-6"print(f"anthropic SDK {anthropic.__version__}, model {MODEL}")anthropic SDK 0.84.0, model claude-sonnet-4-6# Force-reload the corpus module in case this kernel has a stale cached versionimport importlib
import research_corpus
importlib.reload(research_corpus)from research_corpus import COMPACTION_PROBES, CORPUS
# Count tokens via the API (cached in-memory so repeat kernel runs are fast)._token_cache: dict[str, int] = {}
def count_tokens(text: str) -> int: if text not in _token_cache: _token_cache[text] = client.messages.count_tokens( model=MODEL, messages=[{"role": "user", "content": text}] ).input_tokens return _token_cache[text]
print(f"CORPUS is a dict of {len(CORPUS)} synthetic documents held in Python memory.")print("When the agent calls read_file, the content is served from this dict and")print("lands directly in the agent's context window — no disk I/O involved.")_total_tokens = 0for path, content in CORPUS.items(): n_tok = count_tokens(content) _total_tokens += n_tok # Strip the virtual directory prefix for display clarity display_name = path.removeprefix("/research/") print(f" {display_name:<26} ~{n_tok:>6,} tokens")print(f" Total corpus: ~{_total_tokens:,} tokens")
# Sanity check: the corpus should be large enough to push context well past# 200K in a single read-pass. If this fires, research_corpus.py may be stale.assert _total_tokens > 250_000, ( f"Corpus is only {_total_tokens:,} tokens; expected >250K. " "Restart the kernel and re-run, or verify research_corpus.py is current.")CORPUS is a dict of 8 synthetic documents held in Python memory.When the agent calls read_file, the content is served from this dict andlands directly in the agent's context window — no disk I/O involved.
celegans_review.md ~41,260 tokens drosophila_review.md ~41,200 tokens mouse_review.md ~41,155 tokens zebrafish_review.md ~41,095 tokens killifish_review.md ~41,115 tokens yeast_review.md ~41,101 tokens nmr_review.md ~41,017 tokens rhesus_review.md ~41,012 tokens
Total corpus: ~328,955 tokens问题:一个长期运行的研究代理
本 Cookbook 中的代理扮演的是一位生物学科研人员,撰写一篇关于模式生物用于衰老与长寿研究的比较综述。这个任务足够真实、足够有分量:它需要通读一批综述文档(每种生物一篇),抽取可比的事实(寿命、遗传可操作性、与人类的转化相关性),做结构化笔记,并把读到的所有内容综合成文。
这类工作正是上下文管理开始吃紧的地方。每篇文档约 4 万词元(正文加大量附录干预数据表),任务要求代理分两批阅读:先读四种高通量生物(C. elegans、Drosophila、yeast、killifish),再读四种低通量生物(mouse、zebrafish、naked mole-rat、rhesus)。两批结构是本 Cookbook 的实验设计选择:它产生的上下文轨迹在第一批就会越过压缩触发线,在第二批越过 200K 参考线,于是每种原语对轨迹的影响能在同一次运行中显现。不做上下文管理的话,代理的上下文会在任务中途增长到数十万词元。而由于工作跨越多个会话,即使某次运行顺利完成,下一次会话开始时也对已学到的内容毫无记忆。
研究任务
代理的具体任务:在三个维度上比较 /research/ 中的模式生物(寿命与实验通量、遗传可操作性、与人类衰老的转化相关性),分两批读完八篇综述文档并边读边记笔记,最后写出一篇比较性的综合综述。
三个 API 如何对应问题
每个 API 针对的是不同类型的上下文增长。弄清自己面对的是哪一种,是选对工具的第一步。
概念层面
**压缩(compaction)**的做法是:把接近上下文窗口上限的对话拿出来,总结其内容,再以这份摘要重新开始。它的目标是以高保真的方式蒸馏上下文窗口,让代理能带着最小的性能损失继续。压缩的艺术在于保留什么、舍弃什么:过度激进的压缩可能丢失微妙但关键、其重要性要到后来才显现的上下文。摘要会保留架构决策、未解决的问题和关键事实,同时丢弃冗余内容;它天生有损(lossy),但能处理所有的上下文增长,而不只是工具结果。压缩是*整段转录(whole-transcript)*级别的操作:用户消息、助手消息、工具调用、工具结果,甚至早先的压缩块,统统被压平进摘要。
**工具结果清理(tool-result clearing)**则相反,是*子转录(sub-transcript)*级别的操作。它遍历消息列表,精准地替换 tool_result 内容块,其余一切——用户消息、助手的推理、tool_use 记录——原封不动。代理调用工具后,结果成为对话历史的一部分,在随后的每一轮都计入上下文预算。其中大量内容是可重新获取的:文件内容代理可以重读,API 响应可以重新请求。清理把旧的 tool_result 块替换成一段简短的占位符,保留 tool_use 记录,让模型仍然知道自己做过那次调用,但丢掉体积庞大的负载。工具一旦在消息历史深处被调用过,代理很少需要再看一遍原始结果;清理是回收这部分空间最安全、侵入性最小的方式之一。如果代理确实需要那些数据,直接再调用一次工具即可。
记忆(memory),即结构化记笔记,是一种让代理定期把笔记写到上下文窗口之外、之后再按需取回的技术。它以极小的开销提供持久记忆:代理可以跨复杂任务追踪进度,保住那些本会散落在几十次工具调用之间、或在上下文重置时丢失的关键上下文。在一次重置之后(新会话,或压缩之后),代理读回自己的笔记继续推进。存储后端由你实现,因此存什么、存多久都由你掌控。
除了启用这些原语,理解如何最有效地实现它们同样重要:默认行为能让你起步,但压缩摘要的质量、以及最终落进记忆的内容有没有用,都取决于你提供的引导。下文每个原语的小节里都包含”如何有效实现”的讨论。
操作层面
| API | 标识符(Identifier) | Beta 请求头(Beta header) | 触发方式 | 可配置旋钮 |
|---|---|---|---|---|
| 压缩(Compaction) | compact_20260112 | compact-2026-01-12 | 词元阈值(服务端,最低 50K) | trigger(默认 150K)、instructions、pause_after_compaction |
| 工具结果清理(Tool clearing) | clear_tool_uses_20250919 | context-management-2025-06-27 | 词元阈值(服务端) | trigger(默认 100K)、keep(默认保留 3 次工具调用)、clear_at_least、exclude_tools、clear_tool_inputs |
| 记忆工具(Memory tool) | memory_20250818 | 无(独立) | 由模型触发(它本身是一次工具调用) | 客户端实现:view、create、str_replace、insert、delete、rename |
对应到研究代理
具体到本 Cookbook 的研究代理,三个问题干净利落地一一对应:
- 代理的实时解说(“C. elegans 是 18 天寿命、可全基因组 RNAi,小鼠是 30 个月但每队列要 10 万美元……”)加上用户的追问,累积成一段很长的对话。这是压缩问题。
- 读完八篇约 4 万词元的综述文档,会产生约 32 万词元的工具结果体量,足以进入上下文衰退导致模型性能衰减的范围。其中大部分代理都可以按需重读。这是清理问题。
- 工作跨越多个会话。如果会话 1 确定了 killifish 是最短命的脊椎动物(4–6 个月),我们希望会话 2 能保留这一发现并在此基础上推进,而不是从头再发现一遍。这是记忆问题。
一个粗略的取舍心智模型:压缩在窗口变得过大时压缩整个窗口;清理丢弃窗口内过时的、可重新获取的数据;记忆把信息移出窗口,让它能跨会话存续。每一层都会增加需要调优的配置和需要理解的相互作用,所以值得从与你实际观察到的瓶颈相匹配的那一种开始。
研究代理
在探索每种原语之前,我们先搭建代理本身:工具 schema、工具执行,以及一个无论是否带上下文管理配置都能运行的代理循环。全部以内联方式给出,方便你看清完整循环。
# ── Tool schemas ─────────────────────────────────────────────────────────RESEARCH_TASK = """Compare the model organisms in /research/ on three dimensions:1. Lifespan and experimental throughput (how fast can you get a lifespan result?)2. Genetic tractability (what tools exist for manipulation and screening?)3. Translational relevance (how well do findings transfer to human aging?)
Work through the organisms in two batches, recording a note after eachbatch before moving on:
BATCH 1 (high-throughput models): Read celegans_review.md,drosophila_review.md, yeast_review.md, and killifish_review.md. Record asingle detailed note covering all four organisms on all three dimensions.Do not begin Batch 2 until this note is recorded.
BATCH 2 (low-throughput models): Read mouse_review.md,zebrafish_review.md, nmr_review.md, and rhesus_review.md. Record asingle detailed note covering all four organisms on all threedimensions.
After both batches, write a comprehensive comparative synthesiscontrasting the high-throughput and low-throughput models."""
BASE_TOOLS: list[dict] = [ { "name": "search_files", "description": "Search document filenames and contents for a keyword. Returns matching paths with a short excerpt.", "input_schema": { "type": "object", "properties": {"query": {"type": "string", "description": "Search term"}}, "required": ["query"], }, }, { "name": "read_file", "description": "Read the full content of a document by path.", "input_schema": { "type": "object", "properties": { "path": {"type": "string", "description": "e.g. /research/celegans_review.md"} }, "required": ["path"], }, }, { "name": "record_finding", "description": "Record a research finding (freeform text). Findings are held for the duration of this session only; they are not persisted across sessions.", "input_schema": { "type": "object", "properties": {"finding": {"type": "string"}}, "required": ["finding"], }, },]
# The memory tool spec is defined here but only added to the agent's tool# list when a memory_handler is passed to run_research_session. Baseline# and clearing/compaction runs do NOT get the memory tool.MEMORY_TOOL_SPEC = {"type": "memory_20250818", "name": "memory"}
SYSTEM_PROMPT = """You are a biology research analyst writing a comparative review of model organisms for aging research.
Work systematically: search and read review documents, take notes on key facts (lifespans, genetic tools, translational strengths and caveats), and build a comparative picture.
Be concise in your reasoning text; the goal is notes, not essays."""# ── Tool execution ───────────────────────────────────────────────────────def execute_research_tool(name: str, tool_input: dict, notes: list[str]) -> str: if name == "search_files": query = tool_input.get("query", "").lower() if not query: return "Error: query is required." hits: list[str] = [] for path, content in CORPUS.items(): if query in path.lower() or query in content.lower(): for line in content.split(""): if query in line.lower(): hits.append(f" {path} → {line.strip()[:120]}") break else: hits.append(f" {path}") return ( f"Found {len(hits)} match(es):" + "".join(hits) if hits else f"No matches for '{query}'." )
if name == "read_file": path = tool_input.get("path", "") content = CORPUS.get(path) if content is None: return f"Error: '{path}' not found. Available: {', '.join(CORPUS.keys())}" return content
if name == "record_finding": finding = tool_input.get("finding", "") notes.append(finding) return f"Finding #{len(notes)} recorded (session-local)."
return f"Error: unknown tool '{name}'"# ── Session result container ─────────────────────────────────────────────SessionResult = namedtuple( "SessionResult", [ "messages", # final message list "notes", # notes taken this session "token_trajectory", # list of (turn, total_context_tokens) "events", # list of dicts describing compaction / clearing events "tool_counts", # dict of tool_name -> call count "file_reads", # list of (turn, path) for each read_file call "hit_limit", # True if the session stopped because it hit the context window "final_text", # final assistant text (convenience) ],)
def _format_tool_arg(name: str, tool_input: dict) -> str: """Human-readable one-line summary of a tool call's arguments for verbose output.""" if name == "search_files": return repr(tool_input.get("query", "")) if name == "read_file": return tool_input.get("path", "?") if name == "record_finding": finding = tool_input.get("finding", "") preview = finding[:50].replace("", " ") return f'"{preview}{"..." if len(finding) > 50 else ""}"' if name == "memory": cmd = tool_input.get("command", "?") path = tool_input.get("path", tool_input.get("old_path", "")) return f"{cmd} {path}" return str(tool_input)[:60]
# ── Agent loop ───────────────────────────────────────────────────────────def run_research_session( initial_prompt: str, *, context_management: dict | None = None, betas: list[str] | None = None, memory_handler=None, max_turns: int = 12, label: str = "session", verbose: bool = True,) -> SessionResult: """Run the research agent. Catches context-window overflow gracefully.""" tools = list(BASE_TOOLS) if memory_handler is not None: tools.append(MEMORY_TOOL_SPEC)
messages: list[dict] = [{"role": "user", "content": initial_prompt}] notes: list[str] = [] token_trajectory: list[tuple[int, int]] = [] events: list[dict] = [] tool_counts: dict[str, int] = {} file_reads: list[tuple[int, str]] = [] # (turn, path) for each read_file hit_limit = False final_text = ""
if verbose: print(f"┌─ [{label}]")
for turn in range(1, max_turns + 1): kwargs: dict = dict( model=MODEL, max_tokens=4096, system=SYSTEM_PROMPT, tools=tools, messages=messages, ) if context_management: kwargs["context_management"] = context_management if betas: kwargs["betas"] = betas
# Call the API; catch context-window overflow try: if betas: response = client.beta.messages.create(**kwargs) else: response = client.messages.create(**kwargs) except anthropic.BadRequestError as e: # Context window exceeded (or similar input-too-large error) hit_limit = True if verbose: print(f"│ ⚠ CONTEXT WINDOW LIMIT REACHED at turn {turn} (API rejected)") print(f"│ {str(e)[:200]}") break
# Track TOTAL context size: uncached + cache-read + cache-created. # usage.input_tokens alone excludes cached tokens, which makes the # plot show dips that are just cache hits, not context management. u = response.usage total_in = ( u.input_tokens + (getattr(u, "cache_read_input_tokens", None) or 0) + (getattr(u, "cache_creation_input_tokens", None) or 0) ) token_trajectory.append((turn, total_in))
# Surface context-management events on their own prominent lines cm = getattr(response, "context_management", None) if cm is not None and getattr(cm, "applied_edits", None): for edit in cm.applied_edits: cleared_uses = getattr(edit, "cleared_tool_uses", None) cleared_toks = getattr(edit, "cleared_input_tokens", None) events.append( { "turn": turn, "kind": "clearing", "cleared_tool_uses": cleared_uses, "cleared_input_tokens": cleared_toks, } ) if verbose: print( f"│ ✂ CLEARING (turn {turn}): {cleared_uses or '?'} tool results cleared, " f"~{cleared_toks:,} tokens freed" if cleared_toks else f"│ ✂ CLEARING (turn {turn}): applied" )
# Serialize assistant content, track tool calls and compaction serialized: list[dict] = [] tool_calls: list[dict] = [] turn_tool_calls: list[tuple[str, dict]] = [] # (name, input) for verbose display compaction_this_turn = False for block in response.content: if block.type == "text": serialized.append({"type": "text", "text": block.text}) if block.text.strip(): final_text = block.text elif block.type == "tool_use": serialized.append( { "type": "tool_use", "id": block.id, "name": block.name, "input": block.input, } ) tool_calls.append({"id": block.id, "name": block.name, "input": block.input}) turn_tool_calls.append((block.name, block.input)) tool_counts[block.name] = tool_counts.get(block.name, 0) + 1 # Track file reads specifically so we can show what clearing drops if block.name == "read_file": file_reads.append((turn, block.input.get("path", "?"))) elif block.type == "thinking": serialized.append( {"type": "thinking", "thinking": block.thinking, "signature": block.signature} ) elif block.type == "compaction": serialized.append({"type": "compaction", "content": block.content}) events.append({"turn": turn, "kind": "compaction", "summary": block.content}) compaction_this_turn = True if verbose: print( f"│ ⊟ COMPACTION (turn {turn}): " f"~{count_tokens(block.content):,}-token summary replaces prior turns" ) messages.append({"role": "assistant", "content": serialized})
if not tool_calls: if verbose and not compaction_this_turn: print(f"│ turn {turn:2d} ctx={total_in:>7,} (final answer)") break
# Execute tools, collecting result sizes so the verbose print # can show how much each call added to context tool_results: list[dict] = [] result_sizes: list[int] = [] for call in tool_calls: if call["name"] == "memory" and memory_handler is not None: result = memory_handler.handle(call["input"]) else: result = execute_research_tool(call["name"], call["input"], notes) tool_results.append( { "type": "tool_result", "tool_use_id": call["id"], "content": result, } ) result_sizes.append(len(result) if isinstance(result, str) else 0) messages.append({"role": "user", "content": tool_results})
if verbose and not compaction_this_turn: # Header with context size, then one line per tool call with # its argument and approximate result size (so you can see # which calls are responsible for the next turn's ctx jump) print(f"│ turn {turn:2d} ctx={total_in:>7,}") for (name, tinput), rsize in zip(turn_tool_calls, result_sizes, strict=False): size_note = f" → ~{rsize // 4:,} tok" if rsize > 200 else "" print(f"│ {name:<16} {_format_tool_arg(name, tinput)}{size_note}")
if verbose: if token_trajectory: peak = max(t for _, t in token_trajectory) status = "⚠ HIT CONTEXT LIMIT" if hit_limit else "completed" print( f"└─ {status}: {len(token_trajectory)} turns, peak ctx {peak:,}, " f"final ctx {token_trajectory[-1][1]:,}, {len(events)} context event(s)" ) else: print("└─ HIT CONTEXT LIMIT on first turn: 0 turns completed")
return SessionResult( messages, notes, token_trajectory, events, tool_counts, file_reads, hit_limit, final_text )
def show_cleared_reads(result: SessionResult, keep: int): """Show which file reads are no longer in context after clearing.
Clearing replaces tool results older than the last `keep` tool uses with placeholders. We reconstruct the tool-use order and mark any read that falls outside the surviving `keep`-window as cleared.
Note: if clearing fires multiple times, only the last event's boundary is considered and earlier cleared-then-re-read files may be misclassified. """ if not result.file_reads: print("No file reads in this session.") return clearing_events = [e for e in result.events if e["kind"] == "clearing"] if not clearing_events: print("Clearing never fired; all file reads remain in context.") return
# Walk messages in order to reconstruct the sequence of tool_use blocks # and which turn each one came from. The last `keep` of these survive # the most recent clearing; earlier ones are cleared. tool_use_seq: list[tuple[int, str, str]] = [] # (turn, name, path-if-read) turn = 0 for msg in result.messages: if msg["role"] == "assistant" and isinstance(msg["content"], list): turn += 1 for block in msg["content"]: if block.get("type") == "tool_use": name = block.get("name", "?") path = block.get("input", {}).get("path", "") if name == "read_file" else "" tool_use_seq.append((turn, name, path))
last_clear_turn = clearing_events[-1]["turn"] seq_before = [t for t in tool_use_seq if t[0] < last_clear_turn] cleared_reads = [(t, p) for (t, n, p) in seq_before[:-keep] if n == "read_file"] surviving_reads = [ (t, p) for tu in seq_before[-keep:] for (t, n, p) in [tu] if n == "read_file" ] # Reads at or after the last clearing turn are untouched by it. surviving_reads += [ (t, p) for (t, n, p) in tool_use_seq if t >= last_clear_turn and n == "read_file" ]
total = len(result.file_reads) print(f"Total file reads across session: {total}") print(f"Last clearing event fired at turn {last_clear_turn} (keep={keep})") print(f"Reads cleared from context: {len(cleared_reads)}") for turn, path in cleared_reads[:12]: print(f" ✗ turn {turn:2d}: {path}") if len(cleared_reads) > 12: print(f" ... and {len(cleared_reads) - 12} more") print( f"Reads still in context (within the keep={keep} window or after " f"the last clearing): {len(surviving_reads)}" ) for turn, path in surviving_reads[:6]: print(f" ✓ turn {turn:2d}: {path}") if len(surviving_reads) > 6: print(f" ... and {len(surviving_reads) - 6} more")
# ── Plot helpers ─────────────────────────────────────────────────────────
def plot_trajectories( results: dict[str, SessionResult], title: str = "Context size per turn", triggers: dict[str, int] | None = None, project_growth_for: str | None = None,): """Line plot of context tokens per turn.
Vertical dashed lines mark turns where clearing fired; dash-dot lines mark compaction. Horizontal dotted lines mark configured trigger thresholds (pass triggers={"clearing": 20000, "compaction": 50000} etc).
project_growth_for: label of a run to extrapolate. Fits a line to the last 5 points and draws a dotted segment forward ~8 turns to show where unmanaged growth is heading. """ fig, ax = plt.subplots(figsize=(10, 4.5)) colors = plt.rcParams["axes.prop_cycle"].by_key()["color"]
for i, (label, res) in enumerate(results.items()): turns = [t for t, _ in res.token_trajectory] tokens = [tok for _, tok in res.token_trajectory] color = colors[i % len(colors)] ax.plot(turns, tokens, marker="o", label=label, markersize=4, color=color) # Mark events on the x-axis for ev in res.events: style = "--" if ev["kind"] == "clearing" else "-." ax.axvline(x=ev["turn"], color=color, linestyle=style, alpha=0.25, linewidth=1) # Dotted growth projection for the named run, capped at 1M if label == project_growth_for and len(turns) >= 3: HARD_LIMIT = 1_000_000 fit_n = min(5, len(turns)) xs, ys = turns[-fit_n:], tokens[-fit_n:] n = len(xs) sx, sy = sum(xs), sum(ys) slope = (n * sum(x * y for x, y in zip(xs, ys, strict=False)) - sx * sy) / ( n * sum(x * x for x in xs) - sx * sx ) intercept = (sy - slope * sx) / n proj_x, proj_y = [], [] for x in range(turns[-1], turns[-1] + 9): y = slope * x + intercept if y > HARD_LIMIT: # Clip the last segment to the 1M ceiling and stop if proj_y and slope > 0: proj_x.append(proj_x[-1] + (HARD_LIMIT - proj_y[-1]) / slope) proj_y.append(HARD_LIMIT) break proj_x.append(x) proj_y.append(y) if proj_y: ax.plot(proj_x, proj_y, linestyle=":", color=color, alpha=0.6, linewidth=1.5)
# Horizontal reference lines for trigger thresholds if triggers: for name, value in triggers.items(): ax.axhline(y=value, color="gray", linestyle=":", alpha=0.6, linewidth=1) ax.annotate( f"{name} trigger: {value:,}", xy=(ax.get_xlim()[1], value), xytext=(-5, 3), textcoords="offset points", ha="right", va="bottom", fontsize=8, color="gray", )
# 200K reference: earlier models cap here and would hard-stop if ax.get_ylim()[1] > 30_000: ax.axhline(y=200_000, color="gray", linestyle="--", alpha=0.5, linewidth=1) ax.annotate( "200K: earlier models stop here", xy=(ax.get_xlim()[0], 200_000), xytext=(5, -12), textcoords="offset points", ha="left", va="top", fontsize=8, color="gray", alpha=0.8, )
ax.set_xlabel("Turn") ax.set_ylabel("Context tokens (incl. cached)") ax.set_title(title) ax.legend(loc="best") ax.grid(alpha=0.3) plt.tight_layout() plt.show()
def plot_summary_bars(results: dict[str, SessionResult], title: str = "Session outcomes"): """Side-by-side bars: final context, file reads.""" labels = list(results.keys()) final_ctx = [r.token_trajectory[-1][1] for r in results.values()] reads = [r.tool_counts.get("read_file", 0) for r in results.values()]
fig, axes = plt.subplots(1, 2, figsize=(9, 3.5)) fig.suptitle(title, y=1.02)
for ax, values, ylabel in zip( axes, [final_ctx, reads], ["Final context (tokens)", "File reads"], strict=False, ): bars = ax.bar(range(len(labels)), values, color=plt.cm.Set2(range(len(labels)))) ax.set_ylabel(ylabel) ax.set_xticks(range(len(labels))) ax.set_xticklabels(labels, rotation=30, ha="right", fontsize=8) ax.grid(axis="y", alpha=0.3) for bar, val in zip(bars, values, strict=False): ax.text( bar.get_x() + bar.get_width() / 2, bar.get_height(), f"{val:,}" if val > 1000 else str(val), ha="center", va="bottom", fontsize=7, )
plt.tight_layout() plt.show()基线:不做上下文管理
首先,我们在不带任何上下文管理配置的情况下运行代理。面对这么大的语料库(每篇文档连同附录表约 4 万词元),上下文增长很快。我们会从两个视角看同一次运行:在一个 1M 词元窗口上会发生什么,以及在一个 200K 窗口上会发生什么。
第 1 部分:1M 词元窗口
Claude Sonnet 4.6 和 Claude Opus 4.6 都提供1M 词元上下文窗口。对本任务而言,基线的总输入会保持在该上限之内:代理读完整个语料库并完成综合,不会撞上硬墙。下面的轨迹显示运行攀升到数十万词元,虚线投影按同样速率继续增长会到达的位置。
baseline = run_research_session(RESEARCH_TASK, label="baseline", max_turns=12)
plot_trajectories( {"baseline": baseline}, "Baseline on a 1M window: context grows past 200K", project_growth_for="baseline",)
peak = max(t for _, t in baseline.token_trajectory)n_turns = len(baseline.token_trajectory)print(f"Peak context: {peak:,} tokens across {n_turns} turns")print(f"File reads: {baseline.tool_counts.get('read_file', 0)}, Notes: {len(baseline.notes)}")if baseline.hit_limit: print("⚠ This run hit the 1M hard limit.")else: print( "The run stayed within the 1M window. The dotted line projects " "where continued growth at the same rate would land, capped at 1M." )┌─ [baseline]│ turn 1 ctx= 1,058│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/yeast_review.md → ~27,320 tok│ read_file /research/killifish_review.md → ~27,349 tok│ turn 2 ctx=166,043│ record_finding "## BATCH 1 NOTES: High-Throughput Model Organisms ..."│ turn 3 ctx=168,242│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ turn 4 ctx=332,821│ record_finding "## BATCH 2 NOTES: Low-Throughput Model Organisms —..."│ turn 5 ctx=335,279 (final answer)└─ completed: 5 turns, peak ctx 335,279, final ctx 335,279, 0 context event(s)
Peak context: 335,279 tokens across 5 turnsFile reads: 8, Notes: 2
The run stayed within the 1M window. The dotted line projects where continued growth at the same rate would land, capped at 1M.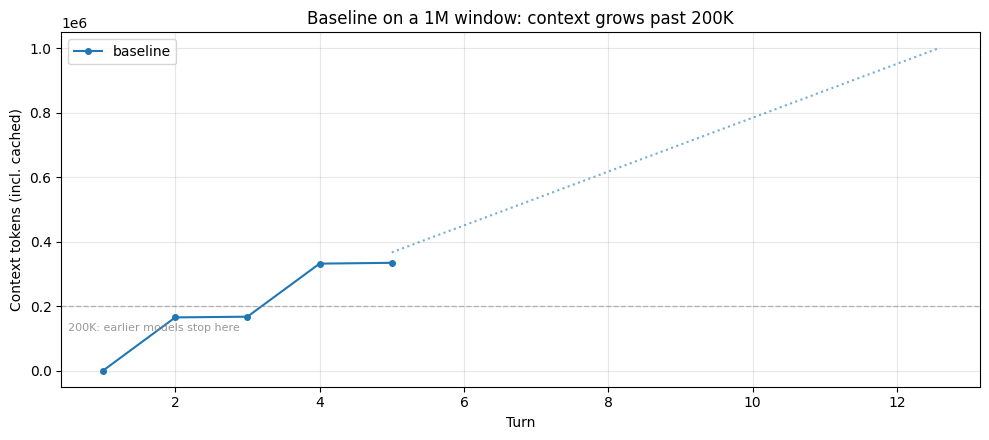
# ── What's actually sitting in the context window at the end of the run ──# Walk the message list and bucket everything by type. This is what the# model has to attend to on every turn: no hard wall stopped it, but the# pile keeps growing and every fact from early turns is buried deeper.
def _bucket_context(messages: list[dict]) -> dict[str, tuple[int, int]]: """Categorize message content into (count, approx_tokens) per bucket.""" buckets: dict[str, list[int]] = { "File-read results": [], "Other tool results": [], "Agent reasoning text": [], "Tool-call records": [], "User/task prompts": [], } for msg in messages: content = msg.get("content") if isinstance(content, str): buckets["User/task prompts"].append(len(content)) elif isinstance(content, list): for block in content: bt = block.get("type") if bt == "tool_result": body = block.get("content", "") body = body if isinstance(body, str) else json.dumps(body) # Heuristic: large tool results are file reads key = "File-read results" if len(body) > 5000 else "Other tool results" buckets[key].append(len(body)) elif bt == "text": buckets["Agent reasoning text"].append(len(block.get("text", ""))) elif bt == "tool_use": buckets["Tool-call records"].append(len(json.dumps(block.get("input", {})))) # chars // 4 as a rough token estimate; the exact number isn't the point return {k: (len(v), sum(v) // 4) for k, v in buckets.items() if v}
print("=" * 72)print("WHAT THE MODEL IS ATTENDING TO at the end of the baseline run")print("=" * 72)breakdown = _bucket_context(baseline.messages)total_est = sum(tok for _, tok in breakdown.values())# Scale the char-based estimates so the total matches the API's reported# context size. This keeps the proportions meaningful and the absolute# numbers consistent with the usage figures shown elsewhere.api_total = baseline.token_trajectory[-1][1]scale = api_total / total_est if total_est else 1.0print(f"Context breakdown ({api_total:,} tokens total per API usage):")for label, (count, tokens) in sorted(breakdown.items(), key=lambda kv: -kv[1][1]): scaled = int(tokens * scale) pct = 100 * tokens / total_est if total_est else 0 print(f" {label:<26} ~{scaled:>8,} tokens ({count:>3} blocks, {pct:4.1f}%)")
if baseline.file_reads: first_turn, first_path = baseline.file_reads[0] doc_name = first_path.split("/")[-1] print(f"First document read: {doc_name} at turn {first_turn}.")========================================================================WHAT THE MODEL IS ATTENDING TO at the end of the baseline run========================================================================
Context breakdown (335,279 tokens total per API usage):
File-read results ~ 322,946 tokens ( 8 blocks, 96.3%) Tool-call records ~ 6,287 tokens ( 10 blocks, 1.9%) Agent reasoning text ~ 5,660 tokens ( 5 blocks, 1.7%) User/task prompts ~ 357 tokens ( 1 blocks, 0.1%) Other tool results ~ 26 tokens ( 2 blocks, 0.0%)
First document read: celegans_review.md at turn 1.上面的分解让规模变得具体。模型在每一轮都携带着数十万词元的文件内容,其中大部分是代理已经处理过并记过笔记的文档。第一篇读入的文档仍在窗口里,但到运行结束时,它已经被压在数十万词元的其他工具结果、以及代理的全部推理和笔记之下。它并没有被移除,只是在和其余一切争夺注意力。上下文衰退就在这里显现:随着窗口被填满,对该深度细节的回忆会退化,即便内容在技术上仍然存在。而且预填充(prefill)延迟随上下文长度增长,每一轮都要付出处理整堆内容的代价。
第 2 部分:200K 词元窗口
早期的模型上限是 200K 词元。在这些模型上,同样的基线运行会撞上一堵硬墙:上下文一旦超过上限,API 就会拒绝下一个请求,任务中途停止。
下面这个单元会找出基线第一次越过 200K 的那一轮,并从 200K 模型的视角展示这次运行的样子:在那之前轨迹完全相同,然后戛然而止。
# No new agent run here. We reuse the Part-1 baseline's token_trajectory# and clip it at the turn where context first exceeded 200K, to show what# the same run would look like from a 200K model's perspective.cross_turn = next((t for t, tok in baseline.token_trajectory if tok > 200_000), None)
if cross_turn is None: print( "Baseline never exceeded 200K tokens this run; a 200K model " "would have seen the same result." )else: # Plot the turns that fit under 200K, plus a dotted segment to the # rejected turn and a red cutoff marker between them. clipped_traj = [(t, tok) for t, tok in baseline.token_trajectory if t < cross_turn] turns_c = [t for t, _ in clipped_traj] toks_c = [tok for _, tok in clipped_traj] rejected_ctx = dict(baseline.token_trajectory).get(cross_turn, 200_000)
fig, ax = plt.subplots(figsize=(10, 4.5)) ax.plot(turns_c, toks_c, marker="o", markersize=4, label="baseline") # Dotted segment from last successful turn to the rejected turn ax.plot( [turns_c[-1], cross_turn], [toks_c[-1], min(rejected_ctx, 200_000)], linestyle=":", color="#1f77b4", alpha=0.6, linewidth=1.5, ) # Hard red vertical line marking the cutoff between the last # successful turn and the rejected one cutoff_x = (turns_c[-1] + cross_turn) / 2 ax.axvline(x=cutoff_x, color="#d62728", linewidth=2) ax.set_xlim(0.5, cross_turn + 0.5) ax.set_ylim(0, 205_000) ax.text( 0.02, 0.96, "context window: 200,000", transform=ax.transAxes, ha="left", va="top", fontsize=9, color="#d62728", ) ax.set_xlabel("Turn") ax.set_ylabel("Context tokens (incl. cached)") ax.set_title("Baseline on a 200K window: agent stopped mid-task") ax.legend(loc="lower right") ax.grid(alpha=0.3) plt.tight_layout() plt.show()
last_turn = clipped_traj[-1][0] last_ctx = clipped_traj[-1][1] reads_done = sum(1 for t, _ in baseline.file_reads if t < cross_turn) notes_at_stop = sum( 1 for m in baseline.messages[: 2 * cross_turn] if isinstance(m.get("content"), list) for b in m["content"] if b.get("type") == "tool_use" and b.get("name") == "record_finding" ) print("⚠ Baseline HIT THE CONTEXT WINDOW LIMIT.") print(f" Completed {last_turn} turns before the API rejected the next request.") print(f" Last successful context: {last_ctx:,} tokens") print(f" File reads attempted: {reads_done}") print(f" Notes taken: {notes_at_stop}") print() print( " The agent stopped mid-task. Without context management, it " "cannot continue past this point." )⚠ Baseline HIT THE CONTEXT WINDOW LIMIT. Completed 3 turns before the API rejected the next request. Last successful context: 168,242 tokens File reads attempted: 8 Notes taken: 2
The agent stopped mid-task. Without context management, it cannot continue past this point.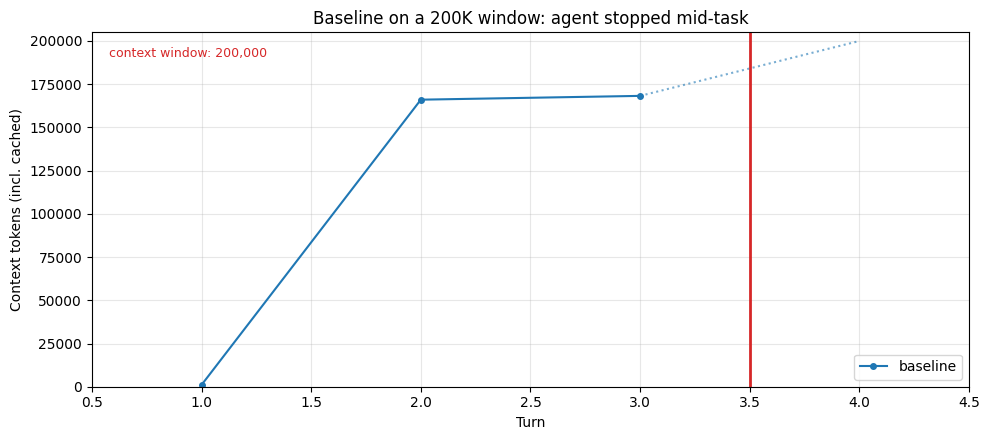
两种失败模式来自同一个根本问题:上下文窗口被数十万词元的文件内容填满,而其中大部分已被处理并记过笔记。不同的是失败的表象。在 200K 窗口上是硬停止
下面介绍的各种原语,正是通过把工作集(working set)控制得足够小,让两种失败模式都不会咬人:窗口填不满,小模型不会停摆,大模型也不会退化。图中都包含 200K 虚线参考线,方便你看出更早的模型会在哪里被截断。
压缩(Compaction)
压缩是管理长对话上下文的实用策略:它把接近上下文窗口上限的对话拿出来,总结其内容,再以这份摘要重新开始。它处理的是代理自身的推理文本、用户的来回对话,以及一个会话过程中做出的决策。更早轮次的具体动作序列和确切措辞不会被保留,但代理达成的目标、做出的决策和主要发现会被总结下来——摘要能保留什么,取决于你的压缩提示词,这一点我们在下面讨论。
压缩的核心是以高保真的方式蒸馏上下文窗口的内容,让代理能带着最小的性能损失继续。取舍在于选择摘要必须保留什么、可以安全丢弃什么:过度激进的压缩可能丢失微妙但关键、其重要性要到后来才显现的上下文。摘要会保留关键决策和事实,但可能丢掉具体数字或确切措辞。它需要推理开销(摘要模型要跑一次),但能处理所有的上下文增长,而不只是工具结果。
底层工作原理
下面是一份最小化的压缩示例实现。我们的官方 API 提供了健壮、经过测试的版本(在词元阈值处自动触发、返回能原生嵌入对话的类型化内容块、正确处理跨摘要边界的工具调用配对),但下面这个约 25 行的版本能把机制讲明白:把对话渲染成文本,让模型总结它,再用这份摘要替换旧消息。
def demo_compact(client, messages: list[dict], model: str) -> list[dict]: """Summarize the conversation and return a fresh message list containing only the summary.""" # Render to a plain-text transcript lines: list[str] = [] for msg in messages: role = msg["role"] content = msg.get("content", "") if isinstance(content, str): lines.append(f"[{role}] {content}") elif isinstance(content, list): for block in content: bt = block.get("type", "?") if bt == "text": lines.append(f"[{role}] {block['text']}") elif bt == "tool_use": lines.append(f"[{role}→tool] {block['name']}({block.get('input', {})})") elif bt == "tool_result": body = block.get("content", "") body = body if isinstance(body, str) else json.dumps(body) lines.append(f"[tool_result] {body[:200]}{'…' if len(body) > 200 else ''}") transcript = "".join(lines)
resp = client.messages.create( model=model, max_tokens=1024, messages=[ { "role": "user", "content": ( "Summarize the following agent transcript, preserving key " "decisions, facts learned, and open threads. Be concise.
" f"<transcript>{transcript}</transcript>" ), } ], ) summary = resp.content[0].text return [{"role": "user", "content": f"[conversation summary]{summary}"}]# Demonstrate on a longer synthetic conversation so the summary is meaningfully shorterdemo_convo = []organisms = [ ( "C. elegans", "18-day median lifespan at 20°C. Survival curve takes 4-6 weeks. Automated platforms handle thousands of animals. Genome-wide RNAi by feeding, fast CRISPR knock-ins. ~40% human orthology, no adaptive immunity, post-mitotic soma.", ), ( "Drosophila", "60-80 day median lifespan at 25°C. Survival curves take 3-4 months. GAL4/UAS tissue-specific expression, FLP/FRT mosaic analysis, mature CRISPR. ~60% human disease gene orthology. Good for cardiac aging and neurodegeneration models.", ), ( "Mouse", "~24-30 month median lifespan. Full study is 3-year commitment, $1-2/day/animal, $100K+ per 100-mouse cohort. Cre-lox conditionals, inbred strain panels, humanized models. ~85% orthology, best translational predictor.", ), ( "Killifish", "4-6 month median lifespan (GRZ strain), shortest-lived vertebrate in the lab. Survival curves under a year. CRISPR works, toolkit still thin. ~70% orthology. Rapid vertebrate aging phenotypes on a compressed timeline.", ), ( "Yeast", "Replicative lifespan ~25 divisions, ~1-2 weeks to result. Genome-wide deletion collection, trivial CRISPR, pooled competitive assays. ~30% orthology. Great for mechanism, not for translation.", ), ( "Naked mole-rat", "Max lifespan >37 years, negligible senescence. No controlled genetics (eusocial breeding). Cell-line studies only. Near-zero cancer incidence. Comparative biology resource, not a screening organism.", ),]for name, facts in organisms: demo_convo.append({"role": "user", "content": f"Tell me about {name} for aging research."}) demo_convo.append({"role": "assistant", "content": f"{name}: {facts}"})demo_convo.append({"role": "user", "content": "What are the key tradeoffs across all of these?"})demo_convo.append( { "role": "assistant", "content": "The core tradeoff is throughput vs. translational relevance. Short-lived invertebrates (worm, fly, yeast) let you screen fast but translate weakly. Mouse is the translational gatekeeper but slow and expensive. Killifish tries to split the difference. The mole-rat is a comparative outlier you study to understand exceptional longevity, not to screen interventions.", })
before_tokens = count_tokens(json.dumps(demo_convo))compacted = demo_compact(client, demo_convo, MODEL)after_tokens = count_tokens(json.dumps(compacted))print( f"Conversation size: ~{before_tokens:,} → ~{after_tokens:,} tokens " f"({(before_tokens - after_tokens) / before_tokens:.0%} reduction)" if after_tokens < before_tokens else f"Conversation size: ~{before_tokens:,} → ~{after_tokens:,} tokens")print(f"Summary produced:{compacted[0]['content'][:800]}")if len(compacted[0]["content"]) > 800: print("...")Conversation size: ~741 → ~449 tokens (39% reduction)
Summary produced:[conversation summary]## Summary: Model Organisms for Aging Research
### Key Facts Learned| Organism | Lifespan | Study Duration | Human Orthology | Standout Feature ||---|---|---|---|---|| *C. elegans* | 18-day median | 4–6 weeks | ~40% | Genome-wide RNAi; high throughput || *Drosophila* | 60–80 days | 3–4 months | ~60% | Tissue-specific genetics; cardiac/neuro models || Mouse | 24–30 months | ~3 years | ~85% | Best translational predictor; expensive ($100K+/cohort) || Killifish | 4–6 months | <1 year | ~70% | Shortest-lived vertebrate; thin toolkit || Yeast | ~25 divisions | 1–2 weeks | ~30% | Mechanistic screening; poor translation || Naked mole-rat | >37 years | N/A | — | Negligible senescence; no genetic control |
### Core Tradeoff**Throughput ↔ Translational relevance** —...上面的示例演示了机制:模型产出一份精简版对话,代理可以从中继续。
使用 API
我们的 API 以 compact_20260112 上下文编辑的形式原生提供此功能。它会在词元阈值处自动触发(最低 50K),返回一个能原生嵌入对话的类型化 compaction 内容块,并处理跨越摘要边界的工具调用配对。压缩触发后,你把压缩块序列化回去({"type": "compaction", "content": block.content}),API 会在下一个请求时丢弃它之前的所有内容。
API 文档:压缩——platform.claude.com
下面是配置了压缩的研究代理运行情况。我们把触发阈值设在 180K,让第一批读取(约 165K)保持在阈值之下:压缩的轨迹在第一批期间与基线重合,当第二批把上下文推到阈值之上时才分道扬镳。留意输出中的 ⊟ COMPACTION 行,以及图中摘要替换旧对话时的骤降。
COMPACTION_TRIGGER = 180_000 # above batch-1's ~165K so the rise is visible before compaction fires
compaction_run = run_research_session( RESEARCH_TASK, betas=["compact-2026-01-12"], context_management={ "edits": [ { "type": "compact_20260112", "trigger": {"type": "input_tokens", "value": COMPACTION_TRIGGER}, } ] }, max_turns=12, label="compaction",)
plot_trajectories( {"baseline": baseline, "compaction": compaction_run}, "Compaction: tracks baseline through batch 1, then summarizes and continues", triggers={"compaction": COMPACTION_TRIGGER},)
compaction_events = [e for e in compaction_run.events if e["kind"] == "compaction"]
# Outcome comparisonprint( f"Baseline: {'HIT LIMIT at' if baseline.hit_limit else 'completed'} " f"turn {len(baseline.token_trajectory)}, " f"peak {max(t for _, t in baseline.token_trajectory):,} tokens")print( f"Compaction: {'HIT LIMIT at' if compaction_run.hit_limit else 'completed'} " f"turn {len(compaction_run.token_trajectory)}, " f"peak {max(t for _, t in compaction_run.token_trajectory):,} tokens, " f"{len(compaction_events)} compaction event(s)")
if compaction_events: for i, ev in enumerate(compaction_events, 1): print( f" Compaction #{i} at turn {ev['turn']}: ~{count_tokens(ev['summary']):,}-token summary" )
baseline_peak = max(t for _, t in baseline.token_trajectory)compaction_peak = max(t for _, t in compaction_run.token_trajectory)print( f"→ Baseline climbed to {baseline_peak:,} tokens; compaction kept " f"the peak at {compaction_peak:,}. On a smaller context window the " f"baseline would have been cut off mid-task; here it completed, but " f"every turn paid to process the full pile.")┌─ [compaction]│ turn 1 ctx= 1,129│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/yeast_review.md → ~27,320 tok│ read_file /research/killifish_review.md → ~27,349 tok│ turn 2 ctx=166,103│ record_finding "## BATCH 1 DETAILED NOTE: High-Throughput Model Or..."│ turn 3 ctx=169,164│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ ⊟ COMPACTION (turn 4): ~2,783-token summary replaces prior turns│ turn 5 ctx= 5,635│ search_files 'comparative aging model organisms synthesis pipeline translational'│ turn 6 ctx= 5,751│ search_files 'aging model organism review'│ turn 7 ctx= 5,829 (final answer)└─ completed: 7 turns, peak ctx 169,164, final ctx 5,829, 1 context event(s)
Baseline: completed turn 5, peak 335,279 tokensCompaction: completed turn 7, peak 169,164 tokens, 1 compaction event(s) Compaction #1 at turn 4: ~2,783-token summary
→ Baseline climbed to 335,279 tokens; compaction kept the peak at 169,164. On a smaller context window the baseline would have been cut off mid-task; here it completed, but every turn paid to process the full pile.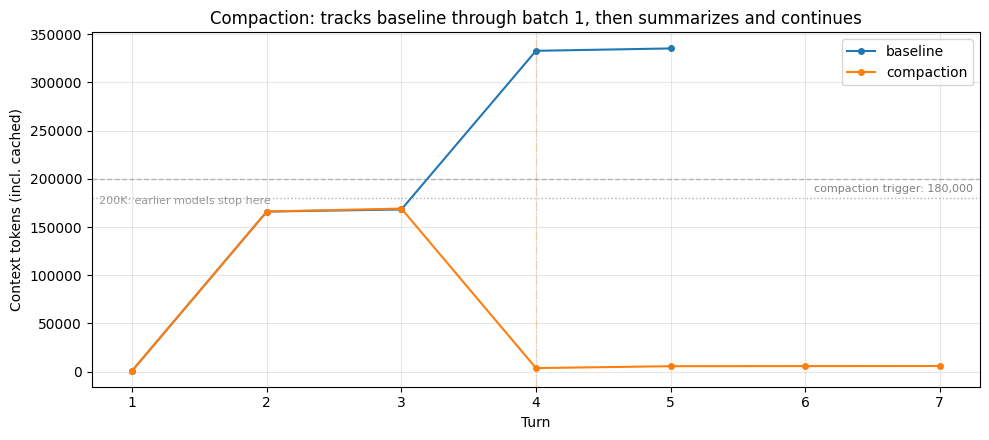
# What compaction costs: check the summary text directly for a MIX of# details. We inspect what the summary PRESERVED, not what the agent# happens to have in context at end-of-run (which could include reads# that happened after compaction fired).compaction_events = [e for e in compaction_run.events if e["kind"] == "compaction"]
print("=" * 70)print("WHAT COMPACTION COSTS: what the summary preserved vs. dropped")print("=" * 70)
if not compaction_events: print("(Compaction did not fire this run; probe skipped)")else: # Use the last compaction summary — it covers the most history. last_ev = compaction_events[-1] summary_text = last_ev["summary"] n_tok = count_tokens(summary_text) print( f"Last compaction at turn {last_ev['turn']} produced a " f"~{n_tok:,}-token summary. The file content read before " f"that point was distilled into this." ) print( "Checking the summary text directly for six details: three " "HIGH-LEVEL facts (central to the task, likely summarized) and " "three OBSCURE specifics (appendix table cells, unlikely to make " "the cut)." )
results = [] for question, answer_key, expected_survive in COMPACTION_PROBES: survived = answer_key.lower() in summary_text.lower() results.append((question, answer_key, expected_survive, survived))
for label, expect in [ ("HIGH-LEVEL FACTS (expected to survive)", True), ("OBSCURE SPECIFICS (expected to be lost)", False), ]: print(f"── {label} ──") for q, key, exp, surv in results: if exp != expect: continue status = "✓ in summary" if surv else "✗ not in summary" print(f" {status:<18} looking for '{key}' — {q}") print()
hl_survived = sum(1 for _, _, e, s in results if e and s) hl_total = sum(1 for _, _, e, _ in results if e) ob_survived = sum(1 for _, _, e, s in results if not e and s) ob_total = sum(1 for _, _, e, _ in results if not e)
print("=" * 70) print( f"RESULT: high-level {hl_survived}/{hl_total} preserved, " f"obscure {ob_survived}/{ob_total} preserved" ) print("=" * 70)
# Show a representative excerpt of the summary so the reader can see # the compression directly. excerpt = summary_text.strip() if len(excerpt) > 600: excerpt = excerpt[:600] + "…" print("Excerpt from the summary (first ~600 chars):") for line in excerpt.splitlines(): print(f" {line}")======================================================================WHAT COMPACTION COSTS: what the summary preserved vs. dropped======================================================================Last compaction at turn 4 produced a ~2,783-token summary. The file content read before that point was distilled into this.
Checking the summary text directly for six details: three HIGH-LEVEL facts (central to the task, likely summarized) and three OBSCURE specifics (appendix table cells, unlikely to make the cut).
── HIGH-LEVEL FACTS (expected to survive) ── ✓ in summary looking for '18' — What is the approximate median lifespan of C. elegans at 20°C? ✓ in summary looking for 'killifish' — Which model organism is the shortest-lived vertebrate used in aging research? ✓ in summary looking for '60' — Roughly what percentage of human disease genes have Drosophila orthologs?
── OBSCURE SPECIFICS (expected to be lost) ── ✗ not in summary looking for '61' — In the appendix Table A5, what is the I-squared heterogeneity value for the NAD+ precursor intervention? ✗ not in summary looking for '55' — In appendix Table A2, what was the effect magnitude for the IIS reduction intervention in cohort 2? ✗ not in summary looking for '0.72' — In appendix Table A7, what is the PhenoAge-like epigenetic clock acceleration ratio under DR for liver tissue?
======================================================================RESULT: high-level 3/3 preserved, obscure 0/3 preserved======================================================================
Excerpt from the summary (first ~600 chars):
## Task Overview I am a biology research analyst writing a comparative review of model organisms for aging research. The task has three phases: 1. **BATCH 1 (DONE):** Read and record a note on four high-throughput models (C. elegans, Drosophila, yeast, killifish) 2. **BATCH 2 (IN PROGRESS):** Read four low-throughput models (mouse, zebrafish, NMR, rhesus) and record a single note — **FILES HAVE BEEN READ, NOTE NOT YET RECORDED** 3. **FINAL:** Write a comprehensive comparative synthesis contrasting both batches
---
## Current State
### Batch 1 — COMPLETE - All four files read: `celegans_revi…分析
基线会一路攀升,直到要么撞上上下文窗口上限(在较小的窗口上是硬停止),要么累积到足以让上下文衰退明显损害回忆的词元量。压缩两者都能应对:当上下文越过触发阈值,旧对话被模型生成的摘要替换,上下文急剧回落。代理带着精简的窗口继续,而不是一个无限膨胀的窗口。
上面的探查直接检查摘要文本里是否含有混合的细节。反复出现的规律是:对任务至关重要的高层事实(代理记下的寿命数字、生物的身份、主要的比较结论)通常能在摘要里幸存;晦涩的细节(附录表里的某个单元格、某个异质性统计量)通常保不住。这与工具结果清理有着有意义的差别:清理是整体丢弃工具结果,内容在被重新获取之前彻底消失;压缩则以压缩形式保留实质内容,但丢失逐字细节。
压缩给你的是让窗口保持精简的通用手段:它把对话和工具结果一起处理,重要的内容以摘要形式存活,代理可以在原本会被截断或淹没的条件下继续工作。它给不了你的是具体细节的逐字保真,或跨会话持久化。如果你的上下文膨胀主要来自可重新获取的工具输出,清理更便宜且无损(代理只要再调一次工具)。如果是无法重新获取的对话和推理,压缩才是对的选择。
如何有效实现压缩
instructions 参数可以让你彻底替换默认的摘要提示词。压缩文档逐字给出了默认提示词:
你已经为上面的初始任务写下了一份不完整的转录稿。请为这份转录稿写一份摘要。这份摘要的目的是提供连续性,让你能在未来的上下文中继续朝着解决任务的方向推进;到那时,上面这些原始历史可能已不可访问,并将被这份摘要取代。请写下任何会有帮助的内容,包括状态、后续步骤、经验教训等。你必须把摘要包在
<summary></summary>块中。
这给了你一个起点。但自定义 instructions 并不会补充这份提示词——而是会完全替换它。所以如果你提供自己的版本,就要负责完整的框架设定。文档中针对编码场景给出的示例是 "Focus on preserving code snippets, variable names, and technical decisions."(聚焦于保留代码片段、变量名和技术决策)。
对本 Cookbook 的研究代理,你可以写一段点名上面探查显示有丢失风险的具体细节的提示词:
context_management={ "edits": [{ "type": "compact_20260112", "trigger": {"type": "input_tokens", "value": 150_000}, "instructions": ( "Summarize this research agent transcript. Preserve every " "quantitative lifespan figure and effect size with its " "source organism, and note which documents have been read " "and which remain. Wrap the summary in <summary></summary>." ), }]}工具结果清理(Tool-Result Clearing)
代理调用工具后,每个结果都会作为一个 tool_result 块追加进对话(上下文编辑文档)。这些块在之后的每一轮都计入输入词元预算,即使代理已经处理完内容、转向了别处。对于可重新调用的工具(文件读取、API 查询、搜索),把逐字结果一直带下去往往没有必要;代理需要时再调一次工具即可。
清理把旧的 tool_result 块替换成一段简短的占位符字符串。其前面的 tool_use 块保留,因此模型仍保有”做过这次调用(以及用什么输入)“的记录,但体积庞大的响应体消失了。这是三种原语里最便宜的:没有推理开销,只是对消息列表做一次机械编辑。
底层工作原理
为了让机制更具体,下面是一份最小化的工具结果清理示例实现。我们的官方 API 提供了健壮、经过测试的版本(自动触发、正确的块配对不变量、工具排除等),但看一下这个约 15 行的版本,核心操作就清晰可见:遍历消息列表,找到 tool_result 块,把除最近几个之外的内容替换成占位符。
def demo_clear_tool_results(messages: list[dict], keep: int = 3) -> int: """Replace the content of all but the last `keep` tool_result blocks. Returns the number of blocks cleared.""" positions: list[tuple[int, int]] = [] for mi, msg in enumerate(messages): if msg.get("role") != "user" or not isinstance(msg.get("content"), list): continue for bi, block in enumerate(msg["content"]): if isinstance(block, dict) and block.get("type") == "tool_result": positions.append((mi, bi))
to_clear = positions[:-keep] if keep > 0 else positions for mi, bi in to_clear: messages[mi]["content"][bi]["content"] = "[cleared to save context]" return len(to_clear)# Demonstrate on a small message list using the actual research corpussample_paths = list(CORPUS.keys())[:3] # first three docs
demo = [{"role": "user", "content": "Read three files and summarize."}]for i, path in enumerate(sample_paths): demo.append( { "role": "assistant", "content": [ {"type": "tool_use", "id": f"t{i}", "name": "read_file", "input": {"path": path}}, ], } ) demo.append( { "role": "user", "content": [ {"type": "tool_result", "tool_use_id": f"t{i}", "content": CORPUS[path]}, ], } )
before_tokens = count_tokens(json.dumps(demo))cleared = demo_clear_tool_results(demo, keep=1)after_tokens = count_tokens(json.dumps(demo))
print(f"Cleared {cleared} of 3 tool results (keep=1 leaves the most recent)")print( f"Message-list size: ~{before_tokens:,} → ~{after_tokens:,} tokens " f"({(before_tokens - after_tokens) / before_tokens:.0%} reduction)")print()print("What each tool_result looks like now:")for _i, msg in enumerate(demo): if not isinstance(msg.get("content"), list): continue for block in msg["content"]: if block.get("type") == "tool_use": print(f" [tool_use] read_file({block['input']['path']})") elif block.get("type") == "tool_result": body = block["content"] if body == "[cleared to save context]": print(f" [tool_result] {body!r} (← cleared)") else: preview = body[:80].replace("", " ") print(f" [tool_result] {preview!r}... (~{count_tokens(body):,} tokens retained)")Cleared 2 of 3 tool results (keep=1 leaves the most recent)Message-list size: ~128,740 → ~43,060 tokens (67% reduction)
What each tool_result looks like now:
[tool_use] read_file(/research/celegans_review.md) [tool_result] '[cleared to save context]' (← cleared)
[tool_use] read_file(/research/drosophila_review.md) [tool_result] '[cleared to save context]' (← cleared)
[tool_use] read_file(/research/mouse_review.md) [tool_result] '# Model Organism Review: Mus musculus in Aging Research The laboratory mouse is'... (~41,155 tokens retained)上面的示例展示了机制。它缺少的是:词元计数与自动触发、正确的 tool_use/tool_result 配对不变量、针对特定工具的排除规则,以及模型侧对”发生过清理”的感知。
使用 API
我们的 API 以 clear_tool_uses_20250919 上下文编辑的形式原生提供此功能。它在服务端处理词元计数与触发,保持块配对,并允许你把特定工具排除在清理之外(当记忆工具同时启用时很有用,稍后我们会看到)。清理触发后,响应会包含 context_management.applied_edits,给出清理了多少次工具使用、释放了多少词元等细节。
还有一个针对扩展思考(extended thinking)块的
clear_thinking_20251015。配置结构相同,type不同。如果两者同时使用,它必须是edits数组中的第一项。
API 文档:上下文编辑——platform.claude.com
下面是启用了清理的研究代理运行情况。基线的上下文随每次文件读取攀升;清理则通过每当上下文越过触发阈值就丢弃旧工具结果,让这次运行保持有界。留意输出中的 ✂ CLEARING 行;图中的虚线竖线标记每次触发。
CLEARING_KEEP = 4 # How many most-recent tool results survive each clearing
clearing_run = run_research_session( RESEARCH_TASK, betas=["context-management-2025-06-27"], context_management={ "edits": [ { "type": "clear_tool_uses_20250919", "trigger": {"type": "input_tokens", "value": 30_000}, "keep": {"type": "tool_uses", "value": CLEARING_KEEP}, "clear_at_least": {"type": "input_tokens", "value": 10_000}, } ] }, label="clearing", max_turns=12,)
plot_trajectories( {"baseline": baseline, "clearing": clearing_run}, "Clearing: stays bounded while the baseline climbs", triggers={"clearing": 30_000},)
# Show outcome comparisonbaseline_turns = len(baseline.token_trajectory)clearing_turns = len(clearing_run.token_trajectory)print( f"Baseline: {'HIT LIMIT at' if baseline.hit_limit else 'completed'} " f"turn {baseline_turns}, peak {max(t for _, t in baseline.token_trajectory):,} tokens")print( f"Clearing: {'HIT LIMIT at' if clearing_run.hit_limit else 'completed'} " f"turn {clearing_turns}, peak {max(t for _, t in clearing_run.token_trajectory):,} tokens")
baseline_peak = max(t for _, t in baseline.token_trajectory)clearing_peak = max(t for _, t in clearing_run.token_trajectory)print( f"→ Baseline climbed to {baseline_peak:,} tokens; clearing kept " f"the peak at {clearing_peak:,}. On a smaller context window the " f"baseline would have been cut off; here both completed, but the " f"baseline was attending to far more on every turn.")
print(f"Clearing events: {len([e for e in clearing_run.events if e['kind'] == 'clearing'])}")print( f"File reads: baseline={baseline.tool_counts.get('read_file', 0)}, " f"clearing={clearing_run.tool_counts.get('read_file', 0)}")┌─ [clearing]│ turn 1 ctx= 1,058│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/yeast_review.md → ~27,320 tok│ read_file /research/killifish_review.md → ~27,349 tok│ turn 2 ctx=166,043│ record_finding "## BATCH 1 NOTES: High-Throughput Model Organisms ..."│ turn 3 ctx=169,211│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ ✂ CLEARING (turn 4): 4 tool results cleared, ~163,817 tokens freed│ turn 4 ctx=169,174│ record_finding ""│ ✂ CLEARING (turn 5): 4 tool results cleared, ~163,811 tokens freed│ turn 5 ctx=169,255│ record_finding ""│ ✂ CLEARING (turn 6): 4 tool results cleared, ~163,807 tokens freed│ turn 6 ctx=169,313│ record_finding "## BATCH 2 NOTES: Low-Throughput Model Organisms (..."│ ✂ CLEARING (turn 7): 4 tool results cleared, ~162,930 tokens freed│ turn 7 ctx=173,137 (final answer)└─ completed: 7 turns, peak ctx 173,137, final ctx 173,137, 4 context event(s)
Baseline: completed turn 5, peak 335,279 tokensClearing: completed turn 7, peak 173,137 tokens
→ Baseline climbed to 335,279 tokens; clearing kept the peak at 173,137. On a smaller context window the baseline would have been cut off; here both completed, but the baseline was attending to far more on every turn.
Clearing events: 4File reads: baseline=8, clearing=8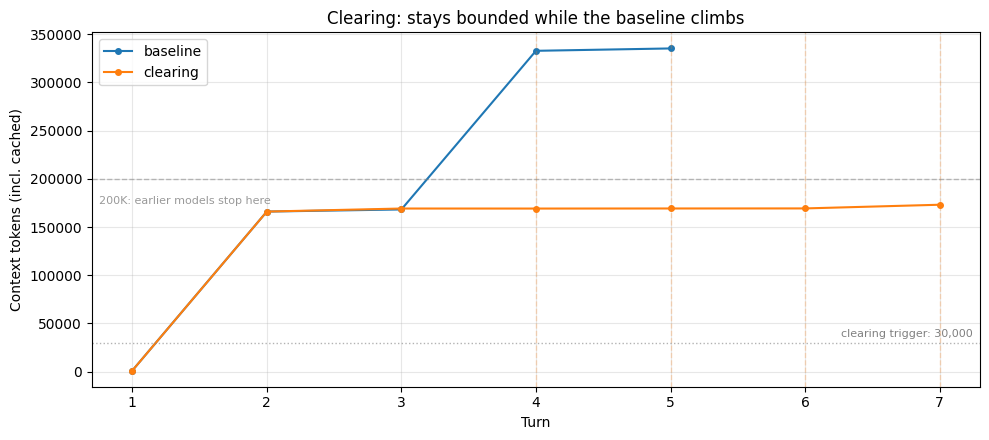
# What's lost: which file reads are no longer in the clearing run's context?print("=" * 60)print("WHAT CLEARING COSTS: reads no longer in context")print("=" * 60)show_cleared_reads(clearing_run, keep=CLEARING_KEEP)print( "The cleared reads above are gone from the conversation. If the " "agent needs that content again, it must call read_file again; the " "information is re-fetchable, but the original read is no longer " "visible in context.")============================================================WHAT CLEARING COSTS: reads no longer in context============================================================Total file reads across session: 8Last clearing event fired at turn 7 (keep=4)
Reads cleared from context: 7 ✗ turn 1: /research/celegans_review.md ✗ turn 1: /research/drosophila_review.md ✗ turn 1: /research/yeast_review.md ✗ turn 1: /research/killifish_review.md ✗ turn 3: /research/mouse_review.md ✗ turn 3: /research/zebrafish_review.md ✗ turn 3: /research/nmr_review.md
Reads still in context (within the keep=4 window or after the last clearing): 1 ✓ turn 3: /research/rhesus_review.md
The cleared reads above are gone from the conversation. If the agent needs that content again, it must call read_file again; the information is re-fetchable, but the original read is no longer visible in context.分析
基线一路攀升;清理运行保持有界。一旦上下文越过触发阈值(这里是 30K),且记录在案的工具使用数超过 keep,清理就在服务端触发:比最近 keep 次更旧的工具结果被替换为占位符,上下文回落。图中的虚线标记每次触发。有界的窗口意味着这次运行在较小的模型上不会撞上硬上限,也不会累积到上下文衰退损害回忆的范围。
上面第二个单元展示了代价。除最近几次外的每次文件读取都从上下文里消失了。当代理进入综合阶段时,它有两条路可走。它可以基于自己的笔记、加上最后一次清理后幸存下来的近期读取来工作:如果笔记详尽,这没问题;如果笔记稀疏,综合就会漏掉代理见过却没记下的细节。或者它可以再次调用 read_file 重新获取被清理的内容:清理运行的读取次数可能比基线对同一批文档的读取更多,因为有些读取在代理用完之前就被清掉了。第二条路要花多大代价取决于你的工具:重读本地文件几乎免费,但重新调用一个限流或很慢的 API 就不是了。调优 keep 和 trigger,就是在调整代理落在这两者之间的位置。
清理给你的是零推理开销的有界窗口,既避开硬上限截断,也避开大上下文累积带来的回忆退化。它给不了你的是对非工具结果内容(代理自身的推理、用户消息)的任何帮助,也不提供任何跨会话持久化。
如何有效实现清理
与压缩和记忆不同,清理没有可调优的提示词,旋钮全是数值(trigger、keep、clear_at_least)或列表(exclude_tools)。有一个需要理解的权衡:清理会使缓存的提示词前缀失效。为抵消这一点,每次应清理足够的词元,让缓存失效物有所值;clear_at_least 参数保证每次清理至少清除一定数量的词元。每次清理触发你都要付出缓存写入成本,但后续请求可以复用新缓存的提示词前缀。
trigger 和 keep 的正确取值取决于你的代理如何使用工具结果:结果有多大、代理多频繁回头查看它们、重新获取是否便宜。上面的清理运行用了 trigger=30K 和 keep=4;稍后的三合一运行会用更高的 trigger 和 keep=6,让清理与压缩分工。针对你自己代理的工作负载测试几组配置:每个响应里的 context_management.applied_edits 字段会显示清理了多少次工具使用、多少词元,让每种配置的效果直接可见。
记忆工具(Memory Tool)
记忆工具让 Claude 能通过一个记忆文件目录跨对话存储和检索信息。Claude 可以创建、读取、更新和删除在会话之间持久化的文件,从而在不把所有内容都塞进上下文窗口的情况下,随时间积累知识。
这是实现即时检索(just-in-time context retrieval)的关键原语:代理不在一开始就把所有相关信息加载进来,而是把学到的东西存进记忆,按需取回。这让活跃上下文始终聚焦于当前相关的内容,对”一次性全加载会压垮窗口”的长期工作流至关重要。清理和压缩都作用于当前上下文;新会话开始、窗口空空如也时,两者都帮不上忙。记忆解决的就是这个问题。
记忆工具在客户端运作
底层工作原理
下面是一份最小化的示例实现:一个键值存储,你在会话结束后写入、在下一个会话开始前读取。我们的官方 API 提供健壮版本(模型在推理过程中自行决定存什么、何时存,完整的文件操作,自动注入的协议提示词),但下面这个约 10 行的版本能把核心模式讲明白。
class SimpleMemoryStore: def __init__(self): self._store: dict[str, str] = {}
def save(self, key: str, value: str) -> None: self._store[key] = value
def load(self, key: str) -> str | None: return self._store.get(key)
def keys(self) -> list[str]: return list(self._store)
# Demonstrate the pattern manuallystore = SimpleMemoryStore()store.save( "lifespans", "C. elegans: ~18 days. Mouse: ~24-30 months. Killifish: 4-6 months (shortest vertebrate).",)store.save( "tractability", "Worm has genome-wide RNAi by feeding. Mouse has Cre-lox conditionals. Killifish toolkit still thin.",)
# In "session 2", you'd inject these into the first prompt:preamble = "".join(f"- {k}: {store.load(k)}" for k in store.keys())print(f"Session-2 opening prompt would include:
Prior research notes:{preamble}")Session-2 opening prompt would include:
Prior research notes:- lifespans: C. elegans: ~18 days. Mouse: ~24-30 months. Killifish: 4-6 months (shortest vertebrate).- tractability: Worm has genome-wide RNAi by feeding. Mouse has Cre-lox conditionals. Killifish toolkit still thin.上面的示例展示了模式,但它把”存什么、何时加载”的决定交到了你手里。而这恰恰是模型更胜任的工作:它在推理中途最清楚哪些事实重要、何时需要回忆它们。
使用 API
我们的 API 以 memory_20250818 工具的形式原生提供此功能。模型在其工具使用循环中自行决定存什么、何时存;一条自动注入的系统提示词确立了协议(“做任何其他事情之前,永远先查看你的记忆目录”);工具提供完整的文件操作而不是键值对。这是一个客户端工具
API 文档:记忆工具——platform.claude.com
下面是一个实现全部六个命令的完整处理器。
class MemoryToolHandler: """Client-side backend for the memory_20250818 tool. Implements view, create, str_replace, insert, delete, rename. File-backed (tempdir) so writes persist across notebook cells. """
def __init__(self, base_dir: str | None = None): self.base = Path(base_dir or tempfile.mkdtemp(prefix="memory_")) self.base.mkdir(parents=True, exist_ok=True)
def _resolve(self, path: str) -> Path: rel = path.removeprefix("/memories").removeprefix("/") or "." resolved = (self.base / rel).resolve() if not str(resolved).startswith(str(self.base.resolve())): raise ValueError(f"path escapes memory directory: {path}") return resolved
def handle(self, tool_input: dict) -> str: cmd = tool_input.get("command") try: if cmd == "view": return self._view(tool_input.get("path", "/memories")) if cmd == "create": return self._create(tool_input["path"], tool_input["file_text"]) if cmd == "str_replace": return self._str_replace( tool_input["path"], tool_input["old_str"], tool_input["new_str"] ) if cmd == "insert": return self._insert( tool_input["path"], tool_input["insert_line"], tool_input["insert_text"] ) if cmd == "delete": return self._delete(tool_input["path"]) if cmd == "rename": return self._rename(tool_input["old_path"], tool_input["new_path"]) return f"Error: unknown command '{cmd}'" except Exception as e: return f"Error: {e}"
def _view(self, path: str) -> str: p = self._resolve(path) if not p.exists(): return ( "Directory /memories is empty." if path in ("/memories", "/memories/") else f"Error: '{path}' does not exist." ) if p.is_dir(): entries = sorted(p.iterdir()) if not entries: return "(empty directory)" return "".join((f"{e.name}/" if e.is_dir() else e.name) for e in entries) content = p.read_text() lines = content.split("") return "".join(f"{i + 1:4d}\t{line}" for i, line in enumerate(lines))
def _create(self, path: str, file_text: str) -> str: p = self._resolve(path) p.parent.mkdir(parents=True, exist_ok=True) p.write_text(file_text) return f"Created {path}"
def _str_replace(self, path: str, old_str: str, new_str: str) -> str: p = self._resolve(path) content = p.read_text() if old_str not in content: return f"Error: old_str not found in {path}" if content.count(old_str) > 1: return f"Error: old_str appears {content.count(old_str)} times; be more specific." p.write_text(content.replace(old_str, new_str, 1)) return f"Replaced in {path}"
def _insert(self, path: str, insert_line: int, insert_text: str) -> str: p = self._resolve(path) lines = p.read_text().split("") lines.insert(insert_line, insert_text) p.write_text("".join(lines)) return f"Inserted at line {insert_line} in {path}"
def _delete(self, path: str) -> str: p = self._resolve(path) if p.is_dir(): import shutil
shutil.rmtree(p) else: p.unlink() return f"Deleted {path}"
def _rename(self, old_path: str, new_path: str) -> str: old_p, new_p = self._resolve(old_path), self._resolve(new_path) new_p.parent.mkdir(parents=True, exist_ok=True) old_p.rename(new_p) return f"Renamed {old_path} → {new_path}"安全提示:
_resolve方法防御路径穿越(path traversal)攻击(如../../etc/passwd)。在生产环境中,你还应该限制文件大小和目录总大小。更深入记忆模式参见记忆 Cookbook。
演示其收益
为了具体看到效果,我们让代理运行三个会话:
- 会话 1 完成初步研究,并把发现写入
/memories。 - 会话 2(无记忆)在空记忆目录下运行一个后续任务。它必须从头重新发现一切。
- 会话 2(有记忆)运行同样的后续任务,但可以访问会话 1 保存的文件。它先读这些文件,并在此基础上推进,而不是重新调研。
两次会话 2 运行的对比,正是记忆收益显现之处。
# Session 1: initial research pass, memory tool enabledmemory = MemoryToolHandler()# Focused task for S1: read a handful of docs, save the comparative findingsS1_TASK = """Compare four model organisms for aging research: C. elegans, mouse,killifish, and yeast. For each one, summarize lifespan, genetic tractability,and translational relevance. Read the review documents and save yourcomparative findings to /memories so a follow-up session can build on them."""
memory_s1 = run_research_session( S1_TASK, memory_handler=memory, max_turns=15, label="memory/s1",)
print("=" * 60)print("What Session 1 wrote to /memories:")print("=" * 60)for f in sorted(memory.base.iterdir()): content = f.read_text() print(f"▸ {f.name} (~{count_tokens(content):,} tokens)") for line in content.split("")[:10]: print(f" {line}") if len(content.split("")) > 10: print(" ...")┌─ [memory/s1]│ turn 1 ctx= 1,941│ memory view /memories│ turn 2 ctx= 2,025│ search_files 'C. elegans aging lifespan'│ search_files 'mouse aging model organism'│ search_files 'killifish aging'│ search_files 'yeast aging replicative chronological'│ turn 3 ctx= 2,386│ search_files 'aging model organism review'│ search_files 'lifespan genetics'│ turn 4 ctx= 2,576│ search_files 'review' → ~205 tok│ search_files 'organism' → ~205 tok│ turn 5 ctx= 3,296│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/killifish_review.md → ~27,349 tok│ read_file /research/yeast_review.md → ~27,320 tok│ turn 6 ctx=168,218│ memory create /memories/aging_model_organisms_comparison.md│ turn 7 ctx=171,354│ record_finding "Four aging model organism reviews fully read and s..."│ turn 8 ctx=171,935 (final answer)└─ completed: 8 turns, peak ctx 171,935, final ctx 171,935, 0 context event(s)
============================================================What Session 1 wrote to /memories:============================================================
▸ aging_model_organisms_comparison.md (~2,999 tokens) # Comparative Notes: Four Model Organisms in Aging Research ## Source files read: /research/celegans_review.md, mouse_review.md, killifish_review.md, yeast_review.md ## Session status: COMPLETE — all four reviews read, notes synthesised
---
## 1. C. elegans (Caenorhabditis elegans)
### Lifespan - Wild-type median: ~18 days at 20°C (N2 strain) ...# Session 2 WITHOUT memory: follow-up task with empty /memories# This shows what happens when the agent has no prior knowledge to draw on.S2_TASK = ( "Write a final synthesis comparing all eight model organisms for " "aging research (C. elegans, Drosophila, yeast, killifish, mouse, " "zebrafish, naked mole-rat, rhesus), focusing on which organisms " "are strongest for which kinds of questions. Use information from " "/memories for organisms already covered there; read source " "documents for any organism not yet captured.")
empty_memory = MemoryToolHandler() # fresh, empty /memoriesmemory_s2_without = run_research_session( S2_TASK, memory_handler=empty_memory, max_turns=12, label="memory/s2-without",)┌─ [memory/s2-without]│ turn 1 ctx= 1,952│ memory view /memories│ turn 2 ctx= 2,056│ search_files 'C. elegans aging model organism'│ search_files 'Drosophila aging model organism'│ search_files 'yeast aging model organism'│ search_files 'killifish aging model organism'│ turn 3 ctx= 2,415│ search_files 'aging model organism lifespan'│ search_files 'mouse aging research'│ search_files 'naked mole-rat longevity'│ search_files 'rhesus macaque aging'│ turn 4 ctx= 2,755│ search_files 'model organism' → ~205 tok│ search_files 'aging research review'│ search_files 'lifespan genetics'│ turn 5 ctx= 3,277│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/yeast_review.md → ~27,320 tok│ read_file /research/killifish_review.md → ~27,349 tok│ turn 6 ctx=168,250│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ turn 7 ctx=332,824│ memory create /memories/organism_notes.md│ turn 8 ctx=333,872│ record_finding "All 8 organism review documents read and key facts..."│ turn 9 ctx=333,977 (final answer)└─ completed: 9 turns, peak ctx 333,977, final ctx 333,977, 0 context event(s)# Session 2 WITH memory: same follow-up task, but with access to Session 1's files# The agent should read /memories first and build on it instead of re-researching.memory_s2 = run_research_session( S2_TASK, memory_handler=memory, # SAME handler as Session 1 max_turns=12, label="memory/s2-with",)
# Show what Session 2 read from /memories in its opening turnsprint("=" * 60)print("What Session 2 (with memory) read from /memories:")print("=" * 60)for msg_i, msg in enumerate(memory_s2.messages[:8]): # Look for memory tool calls in assistant turns if msg["role"] == "assistant" and isinstance(msg["content"], list): for block in msg["content"]: if block.get("type") == "tool_use" and block.get("name") == "memory": inp = block.get("input", {}) print(f"[memory {inp.get('command', '?')}] {inp.get('path', '')}") # Look for the corresponding tool results (what was read) if msg["role"] == "user" and isinstance(msg["content"], list) and msg_i <= 6: for block in msg["content"]: if block.get("type") == "tool_result": result = block.get("content", "") if isinstance(result, str) and len(result) > 20: # Show a preview of what was read preview = result[:350].replace("", " ") print(f" └ {preview}{'...' if len(result) > 350 else ''}")┌─ [memory/s2-with]│ turn 1 ctx= 1,952│ memory view /memories│ turn 2 ctx= 2,043│ memory view /memories/aging_model_organisms_comparison.md → ~2,707 tok│ turn 3 ctx= 5,737│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ turn 4 ctx=170,401│ memory str_replace /memories/aging_model_organisms_comparison.md│ turn 5 ctx=172,415│ record_finding "All eight model organism reviews fully read and sy..."│ turn 6 ctx=172,623 (final answer)└─ completed: 6 turns, peak ctx 172,623, final ctx 172,623, 0 context event(s)
============================================================What Session 2 (with memory) read from /memories:============================================================
[memory view] /memories └ aging_model_organisms_comparison.md
[memory view] /memories/aging_model_organisms_comparison.md └ 1 # Comparative Notes: Four Model Organisms in Aging Research 2 ## Source files read: /research/celegans_review.md, mouse_review.md, killifish_review.md, yeast_review.md 3 ## Session status: COMPLETE — all four reviews read, notes synthesised 4 5 --- 6 7 ## 1. C. elegans (Caenorhabditis elegans) 8 9 ### Lifespan 10 -... └ # Model Organism Review: Drosophila melanogaster in Aging Research
Drosophila melanogaster, the common fruit fly, has been a genetic model for over a century and an aging model since Pearl's demographic work in the 1920s. It occupies a useful middle ground: more complex than C. elegans (tissue diversity, a functional heart, behavioral repertoire) ... └ # Model Organism Review: Danio rerio (Zebrafish) in Aging Research
Zebrafish are a vertebrate model with particular strengths in developmental biology and regeneration that have been increasingly adopted for aging research over the past decade. Their transparent larvae and high fecundity make them competitive with invertebrates for some screening ... └ # Model Organism Review: Heterocephalus glaber (Naked Mole-Rat)
The naked mole-rat is an eusocial rodent from East African burrows with a maximum lifespan exceeding 30 years, roughly ten times that of a similarly sized mouse. It is studied as a model of exceptional longevity rather than as a general aging model: the question is what makes it long-... └ # Model Organism Review: Macaca mulatta (Rhesus Macaque)
Rhesus macaques are the primary non-human primate model for aging research. With a maximum lifespan of ~40 years and physiology closely mirroring human, they represent the closest experimentally accessible approximation to human aging, at correspondingly high cost.
## Lifespan and throughpu...
[memory str_replace] /memories/aging_model_organisms_comparison.md# Compare: the bar chart shows final context and file reads side by side.plot_summary_bars( { "S2 without memory": memory_s2_without, "S2 with memory": memory_s2, }, "Memory benefit: Session 2 with vs. without Session 1's saved findings",)
s2_with_reads = memory_s2.tool_counts.get("read_file", 0)s2_without_reads = memory_s2_without.tool_counts.get("read_file", 0)s2_with_mem = memory_s2.tool_counts.get("memory", 0)s2_without_mem = memory_s2_without.tool_counts.get("memory", 0)
print("Session 2 comparison:")print( f" Without memory: {s2_without_reads} file reads, {s2_without_mem} memory ops, " f"peak ctx {max(t for _, t in memory_s2_without.token_trajectory):,}")print( f" With memory: {s2_with_reads} file reads, {s2_with_mem} memory ops, " f"peak ctx {max(t for _, t in memory_s2.token_trajectory):,}")
if s2_with_reads < s2_without_reads: saved = s2_without_reads - s2_with_reads print( f"→ Memory saved {saved} file read(s): the agent pulled Session 1's " "findings from /memories instead of re-reading the source documents." )elif s2_with_reads == 0 and s2_with_mem > 0: print( "→ Session 2 with memory completed using only /memories; " "no source-document re-reads needed." )else: print( "→ Read counts are similar this run. The benefit depends on how " "comprehensive Session 1's notes were and how the agent chose to use them." )
print( "This comparison shows memory working well because Session 1's notes " "were comprehensive. If Session 1 had saved sparse or poorly organized " "notes, Session 2 would fall back to re-reading source documents. " "Memory's value depends on the agent's judgment about what to write.")Session 2 comparison: Without memory: 8 file reads, 2 memory ops, peak ctx 333,977 With memory: 4 file reads, 3 memory ops, peak ctx 172,623
→ Memory saved 4 file read(s): the agent pulled Session 1's findings from /memories instead of re-reading the source documents.
This comparison shows memory working well because Session 1's notes were comprehensive. If Session 1 had saved sparse or poorly organized notes, Session 2 would fall back to re-reading source documents. Memory's value depends on the agent's judgment about what to write.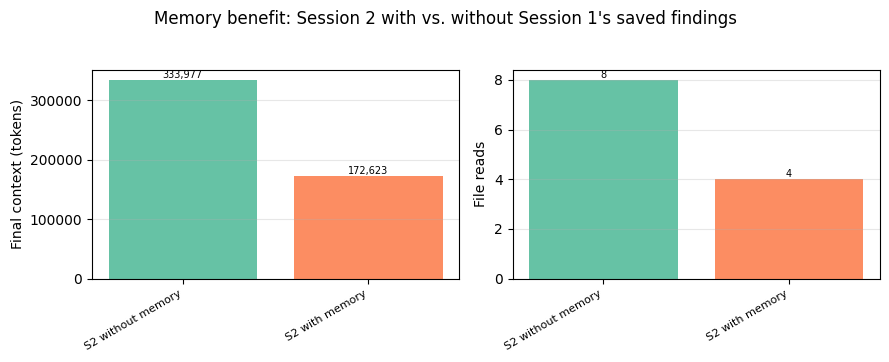
分析
对比让收益变得具体。没有记忆的会话 2 无依无靠;/memories 是空的,它只能回到源文档,重新发现同样的事实。有记忆的会话 2 开场就读 /memories(自动注入的协议让这成为默认的第一步),找到会话 1 保存的发现,就能基于这些内容构建综合报告,而不必重读每一篇源文档。
这正是即时检索的实践:代理不是把所有既往知识都塞进第一个提示词,而是按需从记忆中取回相关片段。条形图里的文件读取次数和最终上下文,直接量化了这一差异。
记忆给你的是跨会话持久化,并且对你选择保存的内容无损保真。它给不了你的是对会话内上下文增长的任何帮助(会话 1 的峰值上下文仍然很高),而且每次读写都会增加工具调用开销。记忆解决的是跨会话问题;清理和压缩解决的是会话内问题。
如何有效实现记忆
memory_20250818 工具会自动注入一条系统提示词,确立”先查记忆”的协议和”假设随时会中断”的心态(“做任何其他事情之前,永远先查看你的记忆目录……你的上下文窗口随时可能被重置”)。这处理了基本机制。除此之外,记忆工具文档描述了塑造模型保存内容的几种方式:
**主题引导。**你可以用一条简单的系统提示词指令来引导写入内容:"Only write down information relevant to <topic> in your memory system."(只在你的记忆系统里写下与<主题>相关的信息。)对本 Cookbook 的研究代理来说,可以是”保存比较性的发现和关键数字,不要保存原始文档内容”。
**保持 /memories 井井有条。**如果观察到模型创建了杂乱无章的记忆文件,试着加上:"when editing your memory folder, always try to keep its content up-to-date, coherent and organized. You can rename or delete files that are no longer relevant. Do not create new files unless necessary."(编辑你的记忆文件夹时,始终努力让内容保持最新、连贯且有条理。你可以重命名或删除不再相关的文件。除非必要,不要创建新文件。)这能防止目录在多个会话间累积半重叠的笔记。
**初始化会话结构。**对多会话工作,可以尝试先跑一个专门的首次会话,在实质性工作开始前就搭建好记忆工件:一份进度日志、一张功能清单、对各类设置脚本的引用。后续会话以读取这些工件开场,从而恢复状态。用这种方式预先铺垫 /memories,能给后续会话一个一致的结构,而不是每个会话都自己发明一套组织方式。
**存储卫生。**在客户端,你还可以追踪文件大小以防无界增长、考虑清理长时间未被访问的记忆文件,并做路径穿越校验。
小结:每种原语的作用
| 原语 | 作用对象 | 牺牲了什么 | 解决什么 |
|---|---|---|---|
| 压缩 | 当前窗口中的整段对话 | 逐字细节被压缩进摘要;晦涩的具体内容可能丢失 | 会话内的一切增长 |
| 清理 | 当前窗口中的工具结果 | 旧工具结果从上下文消失(如需再用必须重新获取) | 工具结果膨胀 |
| 记忆 | 跨窗口的外部存储 | 工具调用开销;质量取决于代理选择保存的内容 | 跨会话持久化 |
下面的图把三次单独运行与基线并排放在一起。注意:记忆的会话 2 是不同的任务(后续综合),因此绝对数值与其他运行不可直接比较;对记忆而言重要的是上面展示的 S2-with 与 S2-without 对比。
# Side-by-side view of each primitive's solo runsolo_results = { "baseline": baseline, "clearing": clearing_run, "compaction": compaction_run, "memory (S2 with)": memory_s2,}plot_summary_bars(solo_results, "Each primitive alone: session outcomes")
# Completion status and events per runprint(f"{'Run':<20} {'Status':<18} {'Context events'}")print("-" * 60)for name, res in solo_results.items(): status = "HIT LIMIT" if res.hit_limit else "completed" n_clear = sum(1 for e in res.events if e["kind"] == "clearing") n_compact = sum(1 for e in res.events if e["kind"] == "compaction") ev_parts = [] if n_clear: ev_parts.append(f"{n_clear} clearing") if n_compact: ev_parts.append(f"{n_compact} compaction") print(f" {name:<18} {status:<18} {', '.join(ev_parts) if ev_parts else 'none'}")Run Status Context events------------------------------------------------------------ baseline completed none clearing completed 4 clearing compaction completed 1 compaction memory (S2 with) completed none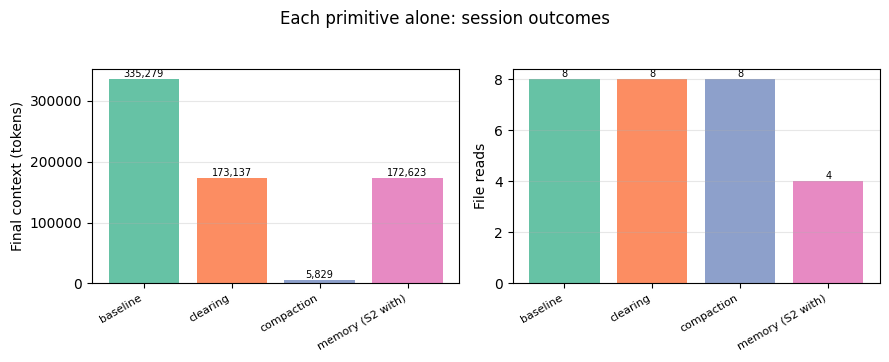
三种原语处理的是上下文问题的不同切片,这正是它们能组合而非竞争的原因。清理和压缩管理当前窗口内部的内容;记忆把信息移出窗口,让它跨会话存续。你需要哪些,取决于你的工作负载实际撞上的是问题的哪些部分。
组合使用它们
三种原语针对上下文问题的不同部分,因此可以叠加使用。Claude Code是一个真实世界的例子,它在采用压缩的同时还配了两套互补的记忆系统:CLAUDE.md 文件保存用户定义的指令和规则(编码规范、项目架构、工作流),由开发者编写并签入源代码管理;自动记忆(auto memory)保存 Claude 自己写下的经验与模式(构建命令、调试心得、从纠正中发现的偏好)。对 Claude Code 而言,两者都是有用的记忆形式。
Claude Code 的设计说明,记忆对同一个代理可以呈现不同形态:一种由用户编写,另一种由模型编写。压缩和清理同理:各自都有配置旋钮(触发阈值、自定义指令、排除哪些工具),让你能针对自己的用例调优行为。这正是上面”如何有效实现”各节中的提示词与配置引导重要的原因:默认行为只是起点,正确的设置取决于你的代理实际在做什么。
关于
exclude_tools的说明:当把清理与记忆工具组合使用时,exclude_tools: ["memory"]设置(见下方配置)可以防止代理的记忆读写被清理。没有它,代理可能丢失”自己刚刚保存了什么”的线索。记忆工具文档在叠加两者时明确建议这么做。
下面我们让研究代理同时启用全部三种原语,并追踪每次原语在会话过程中的作用。
关于配置的说明:两个触发阈值都设得高于第一批的大小(约 167K),让轨迹在第一批期间与基线重合。当第二批把上下文推到约 330K 时,清理先触发(keep=6 丢弃最早的读取,留下约 210K),压缩再作用于清理剩下的内容。记忆全程处于激活状态。这样调参是为了演示,让三种原语在同一次运行中都被激活。生产配置取决于你代理具体的上下文增长模式。
# Both triggers sit above batch-1's ~167K so the rise is visible. At# batch-2 (~330K) clearing fires first (keep=6 drops the earliest 3-4# reads, leaving ~210K) and compaction then fires on what clearing# left. Tuned for demo visibility, not a production recommendation.combo_memory = MemoryToolHandler()COMBO_CLEARING_TRIGGER = 200_000COMBO_COMPACTION_TRIGGER = 180_000
combo_run = run_research_session( """Compare the model organisms in /research/ on lifespan, genetictractability, and translational relevance.
Work in two batches, recording a note after each batch before moving on.Batch 1 (high-throughput): read celegans_review.md, drosophila_review.md,yeast_review.md, killifish_review.md, then record a note. Batch 2(low-throughput): read mouse_review.md, zebrafish_review.md,nmr_review.md, rhesus_review.md, then record a note. Save a comparativesummary to /memories so future sessions can build on it. Finish with adetailed synthesis.""", betas=["context-management-2025-06-27", "compact-2026-01-12"], context_management={ "edits": [ { "type": "clear_tool_uses_20250919", "trigger": {"type": "input_tokens", "value": COMBO_CLEARING_TRIGGER}, "keep": {"type": "tool_uses", "value": 6}, "clear_at_least": {"type": "input_tokens", "value": 30_000}, "exclude_tools": ["memory"], }, { "type": "compact_20260112", "trigger": {"type": "input_tokens", "value": COMBO_COMPACTION_TRIGGER}, }, ], }, memory_handler=combo_memory, max_turns=20, label="all-three",)┌─ [all-three]│ turn 1 ctx= 2,106│ memory view /memories│ turn 2 ctx= 2,206│ read_file /research/celegans_review.md → ~27,465 tok│ read_file /research/drosophila_review.md → ~27,435 tok│ read_file /research/yeast_review.md → ~27,320 tok│ read_file /research/killifish_review.md → ~27,349 tok│ turn 3 ctx=167,185│ memory create /memories/batch1_notes.md│ turn 4 ctx=169,938│ read_file /research/mouse_review.md → ~27,390 tok│ read_file /research/zebrafish_review.md → ~27,363 tok│ read_file /research/nmr_review.md → ~27,287 tok│ read_file /research/rhesus_review.md → ~27,285 tok│ ✂ CLEARING (turn 5): 2 tool results cleared, ~81,993 tokens freed│ ⊟ COMPACTION (turn 5): ~2,839-token summary replaces prior turns│ ✂ CLEARING (turn 6): 2 tool results cleared, ~81,810 tokens freed│ turn 6 ctx= 4,901│ memory view /memories/batch1_notes.md → ~2,370 tok│ ✂ CLEARING (turn 7): 2 tool results cleared, ~81,683 tokens freed│ turn 7 ctx= 8,121│ memory create /memories/batch2_notes.md│ ✂ CLEARING (turn 8): 2 tool results cleared, ~81,508 tokens freed│ turn 8 ctx= 10,524│ memory create /memories/comparative_summary.md│ ✂ CLEARING (turn 9): 2 tool results cleared, ~81,413 tokens freed│ turn 9 ctx= 12,799│ search_files 'translational relevance aging pipeline'│ search_files 'lifespan maximum cohort size intervention'│ ✂ CLEARING (turn 10): 4 tool results cleared, ~162,379 tokens freed│ turn 10 ctx= 13,096│ search_files 'yeast replicative lifespan'│ search_files 'rhesus macaque caloric restriction'│ ✂ CLEARING (turn 11): 4 tool results cleared, ~162,371 tokens freed│ turn 11 ctx= 13,290│ record_finding "All 8 model organisms reviewed and compared. Notes..."│ ✂ CLEARING (turn 12): 4 tool results cleared, ~162,337 tokens freed│ turn 12 ctx= 13,461│ memory str_replace /memories/comparative_summary.md│ ✂ CLEARING (turn 13): 4 tool results cleared, ~162,331 tokens freed│ turn 13 ctx= 13,749 (final answer)└─ completed: 13 turns, peak ctx 169,938, final ctx 13,749, 10 context event(s)# Build a timeline showing when each primitive activated over the sessionprint("=" * 70)print("SESSION TIMELINE: all three primitives active")print("=" * 70)
# Build turn-indexed event markersclear_turns = {e["turn"] for e in combo_run.events if e["kind"] == "clearing"}compact_turns = {e["turn"] for e in combo_run.events if e["kind"] == "compaction"}
# Find per-turn memory tool calls by walking messagesmem_call_turns = set()turn = 0for msg in combo_run.messages: if msg["role"] == "assistant" and isinstance(msg["content"], list): turn += 1 for block in msg["content"]: if block.get("type") == "tool_use" and block.get("name") == "memory": mem_call_turns.add(turn)
# Print turn-by-turn with markersfor t, ctx in combo_run.token_trajectory: markers = [] if t in clear_turns: markers.append("✂ CLEARING") if t in compact_turns: markers.append("⊟ COMPACTION") if t in mem_call_turns: markers.append("◇ memory") marker_str = " " + " ".join(markers) if markers else "" print(f" turn {t:2d} ctx={ctx:>7,}{marker_str}")
# Summary of what each primitive didn_clearing = len(clear_turns)n_compaction = len(compact_turns)n_memory_calls = combo_run.tool_counts.get("memory", 0)mem_files = sorted(combo_memory.base.iterdir())
print("" + "─" * 70)print("What each primitive did this session:")print(f" ✂ Tool-result clearing fired {n_clearing} time(s)")print( f" → Dropped old tool results to keep context capped at ~{max(t for _, t in combo_run.token_trajectory):,} tokens")print( f" → {combo_run.tool_counts.get('read_file', 0)} file reads total " f"(vs baseline's {baseline.tool_counts.get('read_file', 0)}); some were re-fetches after context was reset")
if n_compaction > 0: print(f" ⊟ Compaction fired {n_compaction} time(s)") for ev in combo_run.events: if ev["kind"] == "compaction": print( f" → At turn {ev['turn']}: replaced prior conversation with ~{count_tokens(ev['summary']):,}-token summary" )else: print( f" ⊟ Compaction did not fire (clearing kept context below the {COMBO_COMPACTION_TRIGGER:,} trigger)" )
print( f" ◇ Memory tool called {n_memory_calls} time(s), wrote {len(mem_files)} file(s) to /memories")for f in mem_files: content = f.read_text() print(f" → {f.name} (~{count_tokens(content):,} tokens)") lines = content.split("") for line in lines[:6]: print(f" {line}") if len(lines) > 6: print(" ...")
print("" + "─" * 70)print( f"Peak context: {max(t for _, t in combo_run.token_trajectory):,} tokens " f"(vs baseline's {max(t for _, t in baseline.token_trajectory):,})")print(f"Final context: {combo_run.token_trajectory[-1][1]:,} tokens")print( f"Session {'completed' if not combo_run.hit_limit else 'HIT LIMIT'} " f"in {len(combo_run.token_trajectory)} turns")======================================================================SESSION TIMELINE: all three primitives active====================================================================== turn 1 ctx= 2,106 ◇ memory turn 2 ctx= 2,206 turn 3 ctx=167,185 ◇ memory turn 4 ctx=169,938 turn 5 ctx= 4,798 ✂ CLEARING ⊟ COMPACTION ◇ memory turn 6 ctx= 4,901 ✂ CLEARING ◇ memory turn 7 ctx= 8,121 ✂ CLEARING ◇ memory turn 8 ctx= 10,524 ✂ CLEARING ◇ memory turn 9 ctx= 12,799 ✂ CLEARING turn 10 ctx= 13,096 ✂ CLEARING turn 11 ctx= 13,290 ✂ CLEARING turn 12 ctx= 13,461 ✂ CLEARING ◇ memory turn 13 ctx= 13,749 ✂ CLEARING
──────────────────────────────────────────────────────────────────────What each primitive did this session:
✂ Tool-result clearing fired 9 time(s) → Dropped old tool results to keep context capped at ~169,938 tokens → 8 file reads total (vs baseline's 8); some were re-fetches after context was reset
⊟ Compaction fired 1 time(s) → At turn 5: replaced prior conversation with ~2,839-token summary
◇ Memory tool called 7 time(s), wrote 3 file(s) to /memories → batch1_notes.md (~2,610 tokens) # Batch 1: High-Throughput Model Organisms — Notes
## 1. C. elegans (Caenorhabditis elegans)
### Lifespan - Wild-type median: ~18 days at 20°C (N2 strain) ... → batch2_notes.md (~2,254 tokens) # Batch 2: Vertebrate & Exceptional Longevity Models — Notes
## 5. Mus musculus (Mouse)
### Lifespan - Median: ~24–30 months (C57BL/6J); max ~4.5 yrs (Ames dwarf + CR) ... → comparative_summary.md (~2,173 tokens) # Comparative Summary: Model Organisms for Aging Research
## Quick Reference Table
| Organism | Median Lifespan | Time to Result | Human Orthology | Genetic Tractability | Translational Relevance | Primary Role | |---|---|---|---|---|---|---| ...
──────────────────────────────────────────────────────────────────────Peak context: 169,938 tokens (vs baseline's 335,279)Final context: 13,749 tokensSession completed in 13 turnsplot_trajectories( {"baseline": baseline, "all three active": combo_run}, "All three primitives active: context stays bounded while the session continues", triggers={"clearing": COMBO_CLEARING_TRIGGER, "compaction": COMBO_COMPACTION_TRIGGER},)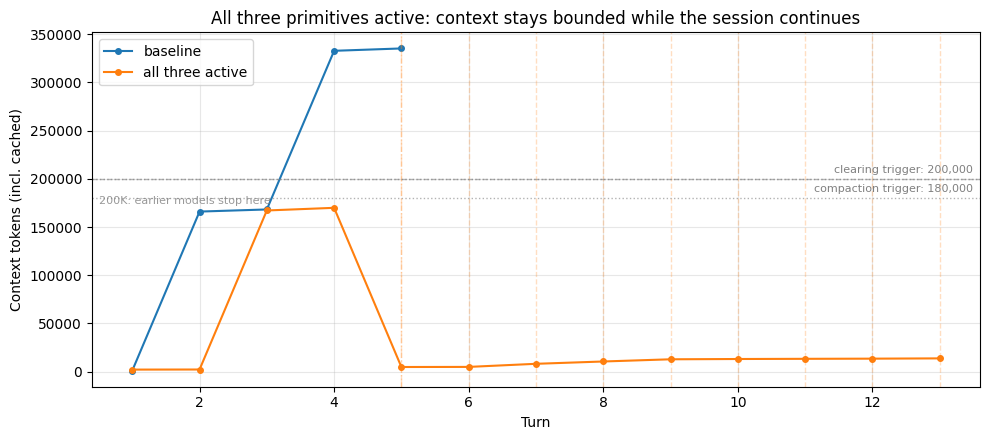
时间线说明了什么
在全部三种原语同时激活时,每种都在会话中因各自的原因被触发。轨迹在第一批期间跟随基线:两个触发阈值都高于第一批的大小,因此直到第二批把上下文推到约 330K 之前,没有任何编辑触发。到那时,清理丢弃最早的读取,压缩总结剩余内容,让代理能继续。记忆全程激活:代理开场检查 /memories,并为未来的会话保存比较笔记。上面的时间线展示了三种原语在一次会话中的协同。
要让这些原语有意义地分工,需要一些调优;建议针对自己的工作负载做取值实验。
重点不在于三者全开能产生”最好”的数字;而在于当问题真正出现时,它们各管一段。有用的问题不是”我该不该三样都用?“,而是”我的工作负载实际遇到了三个问题中的哪一个?”
什么时候可以不用某种原语
不是每种工作负载都需要每种工具。下面是一些你会刻意省掉某一种的情形:
- 想让每个会话都从零开始,就跳过记忆。面向用户的聊天机器人,如果每次对话都应当相互独立,就不需要跨会话持久化;加记忆反而会带上你不想要的状态。
- 如果会话短到天然不会触及上下文上限,就跳过压缩。压缩是有损的(具体细节会被摘要化掉),既然用不上那些余量,就不必为保真度付冤枉钱。
- 如果代理确实需要完整看到过去的工具结果,就跳过清理。做跨文档分析、需要并排比较段落的代理,来不及靠重新获取找回被清理的结果;清理只会逼它做冗余读取。
要点与后续步骤
实验带来的经验
让研究代理在这些不同配置下运行,浮现出几条实用经验:
**轨迹的形状反映了每种工具的作为。**清理触发时,你会看到移除旧工具结果的那一轮出现台阶式下降;在更长的会话里,随着上下文重新爬回触发线,这种现象会重复。压缩每次触发都会带来更大的下降,因为摘要替换的是整整一段轮次,而不只是其中的工具结果。本 Cookbook 的图就是为了让这些效果可见,让你能具体看到转动旋钮后发生的变化。哪种工具适合你的工作负载是另一个问题,取决于代理需要做什么。
**有损性是一条光谱,不是非黑即白。**只要工具可重新调用,清理就是无损的。压缩以可控的方式有损:摘要器提示词(默认或自定义)决定什么能幸存。记忆对已保存的内容无损,但只取决于代理判断该保存什么的水平。每种原语都以不同的方式交换保真度。
**叠加带来的能力与复杂度一样多。**三者同用能覆盖更多上下文问题,但也意味着更多要调的旋钮、更多要追踪的相互作用。在加入一种原语之前,值得先问的问题是:它能解决我工作负载中的哪个具体问题?
**关于更大的上下文窗口。**Sonnet 4.6 和 Opus 4.6 提供 1M 词元上下文,这块余量很有用:更多逐字细节可以留在窗口里,有损操作可以拉开间隔。但正如基线运行的上下文分解所示,1M 模型上的工作集被过时工具结果填满的速度与 200K 模型一样快;区别只在于硬上限的位置,而不是上下文累积的速度。上下文衰退和预填充延迟随窗口内的内容量增长,而不是随窗口上限增长,所以即使硬墙还很远,保持精简的工作集仍然值得。
审视你的工作负载
下表粗略列出了工作负载特征与值得先尝试的原语。把这些当作要在你自己代理上验证的假设,而不是答案。每种工作负载都有表格无法捕捉的特殊之处。
| 如果你的工作负载有…… | 值得先尝试 | 留意 |
|---|---|---|
| 跨越数天或数周的会话 | 记忆工具 | 工具调用开销;事实变化后记忆过时 |
| 需要跨会话学习用户偏好的代理 | 记忆工具 | 隐私/敏感数据策略;用户改主意后偏好过时 |
| 大型、可重新获取的工具结果 | 清理 | 代理重读刚被清理的内容;调优 keep 和 trigger |
| 对话是主要上下文来源 | 压缩 | 具体数字被摘要化而丢失 |
| 不易重新获取的工具结果(临时 API、上传文件) | 优先压缩而非清理 | 这些特定结果的摘要保真度 |
| 每个会话都应从零开始 | 跳过记忆 | 不想要的跨会话状态 |
| 会话远低于窗口上限 | 跳过压缩 | 用不上的有损操作 |
本 Cookbook 未覆盖的内容
**超越基础的调优。**上面”如何有效实现”各节为每种原语给了你一个起点。下一步是实验:不同的用例从同一种原语中得到的价值,会因参数和提示词而异。编码代理和研究代理可能都用压缩,但适合一个的 instructions 字符串未必适合另一个;清理阈值、以及你引导模型往 /memories 里写什么,也是如此。
搭建一个测试脚手架(harness)在这里很有帮助。举个简单的例子:本 Cookbook 的代理循环(run_research_session)返回 token_trajectory、events 和 tool_counts:你可以用几组配置运行你的代理,把轨迹并排画出来,衡量你在意的指标(任务质量、延迟、词元花费)。
相邻特性。程序化工具调用(PTC)通过在模型编写的程序中运行工具,让大型结果根本不进入上下文,这是应对工具膨胀问题的另一种思路。工具搜索(Tool search)能在工具很多时裁剪工具定义的膨胀。
相关阅读
记忆 Cookbook用一个代码审查代理深入探讨记忆模式;压缩 Cookbook单独介绍压缩。想了解多会话软件代理中上下文管理技术的详细案例研究,参见长期运行代理的有效脚手架。
结语
这个 notebook 系统梳理了面向长期运行代理的三种上下文管理原语:用压缩压缩对话历史,用工具结果清理丢弃可重新获取的工具输出,用记忆工具跨会话持久化知识。每种都处理上下文问题的不同切片。
哪些原语对你的代理重要,取决于它的上下文增长实际来自哪里。本 Cookbook 中的配置和代理循环,是让你在自己工作负载上以不同配置运行、观察变化的起点。